Blog

10 best AI web scraping tools in 2026

August 19, 2026

Web scraping platforms, web scraping tools, data extraction platforms, ai scraping platforms
AI can reduce the work required to identify fields, create extraction rules and interpret inconsistent pages. It does not make every scraper equally reliable, nor does it remove the need to handle navigation, JavaScript, blocking, validation and changing websites.

The best AI web scraping tool therefore depends on the job. This guide compares ten leading options across setup, control, dynamic-site support, repeatability, scaling, output and pricing. The aim is not to find one universal winner, but to identify the strongest option for each type of workflow.

Continue Reading

Can AI build a web scraper for you?

August 19, 2026

Web Scraper Cloud, data pipelines, web scraping

Yes. AI can build a useful first version of a web scraper. Depending on the tool and its access, it can inspect a page, identify repeated records, propose fields, generate selectors or write browser-automation code. A coding agent may also run the scraper, observe failures and revise its work.

But creating a scraper is not the same as operating a reliable data pipeline. Repeated clicks, anti-bot restrictions and large workloads still require controlled execution, access infrastructure, validation and monitoring. AI can build the draft. The harder task is proving that it returns complete, correct data at an acceptable cost.

Continue Reading

Web Scraper vs Instant Data Scraper

August 19, 2026

web scraping, browser extension, Web Scraper vs

Web Scraper and Instant Data Scraper are free browser extensions that turn website content into structured data without requiring code. They overlap on simple jobs, but they are designed for different types of work.

Instant Data Scraper is the better choice when the required data already appears as a table or repeated list and you want to export it immediately. Web Scraper is better when the job needs explicit control, linked detail pages, reusable extraction logic or a path to scheduled and scalable Cloud execution.

Continue Reading

Best web scraping test sites

August 18, 2026

Test sites, web scraping sandbox, web scraping practice websites, sites to practice web scraping, scraping test site
A scraper pointed at a load more button finishes in under a second, exits cleanly and writes six records. The category holds several hundred. Nothing errored, no request failed, and the run is marked complete.

That failure is the reason to use a practice site, and it is the thing most lists of them never mention. You get a set of URLs, a note that one holds books and another holds quotes, and no indication of which production problem each one reproduces.

These sites are not interchangeable. A static catalogue of a thousand products tests whether your selectors are correct and whether your crawler reaches the last page. It cannot tell you whether your scraper distinguishes a page that loaded from a page that contains data. The list below is ordered by diagnostic value rather than popularity, and each entry states what the site tests, what it does not, and which production failure it stands in for.

Continue Reading

Scaling web scraping from thousands to millions of pages

August 16, 2026

data pipelines, Web crawling, web scraping, Scraping architecture
A 5 per cent duplicate rate creates 50,000 unnecessary page loads across one million targets. If 10 per cent of those targets fail and every failure receives two retries, the system can generate another 200,000 attempts without collecting a single additional page.

Continue Reading

Incremental web scraping and change detection

August 16, 2026

Web Scraper Cloud, data quality, data pipelines, web scraping, Incremental web scraping, change detection
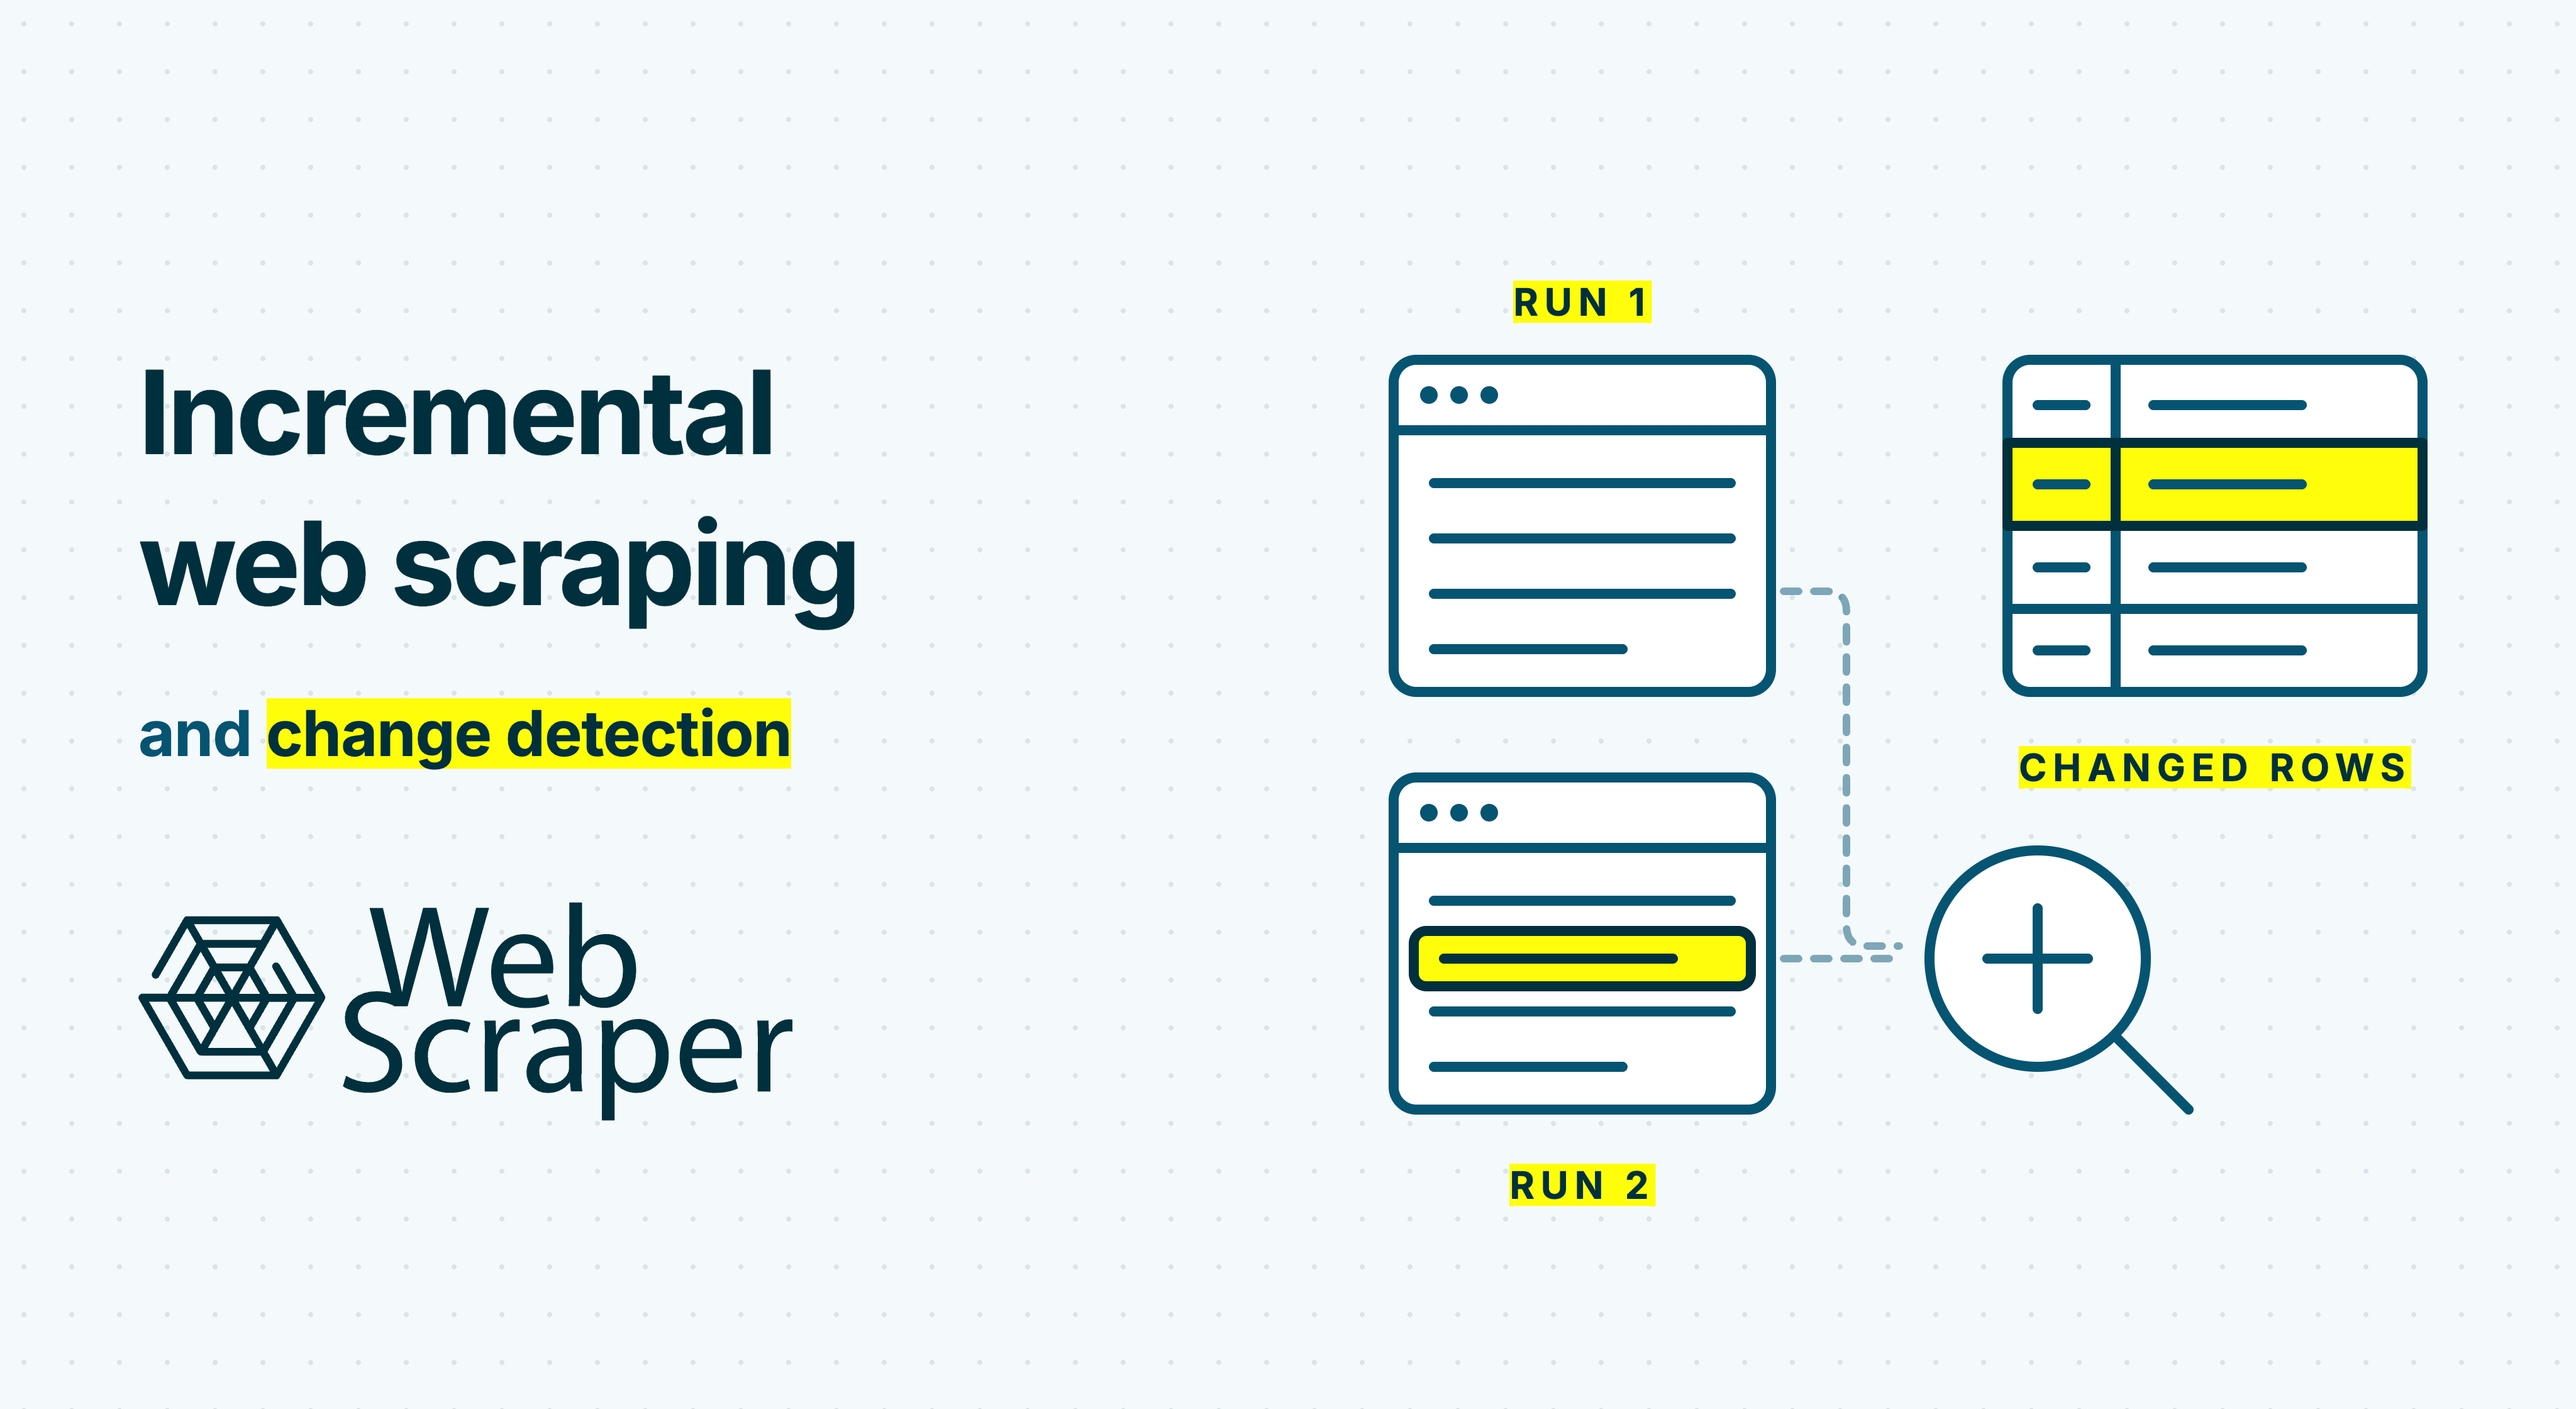
A page can change without the required data changing. The required data can change while the initial HTML remains identical. A record can disappear from one run without being deleted.

Those cases are easy to collapse into a single question: did the page change? A reliable incremental scraping system asks more precise questions. What should be revisited? Which representation contains the required data? Does the new observation differ from trusted prior state? Is that difference meaningful? Is the run reliable enough to publish an update?

Incremental web scraping is therefore a stateful synchronisation problem, not simply a scheduled scrape with a checksum attached. It uses state from earlier runs to reduce unnecessary collection and apply only validated record changes downstream.

Continue Reading

i18n
How Web Scraper was translated into 50 languages with AI

August 13, 2026

i18n

Originally, the Web Scraper extension was only available in English. English is only the third most spoken native language in the world, with 372 million native speakers, while Spanish has 487 million and Chinese has 988 million. To improve usability and reduce misuse, we decided to internationalize the Web Scraper extension. The initial plan was to use a SaaS, but in the end, everything was translated by AI.
Continue Reading

Build vs buy: Should you develop or purchase a web scraper?

August 13, 2026

Web scraping platforms, Web scraper development, Web Scraper Cloud, Scraping infrastructure, Build vs buy
A developer can write a scraper that collects a product name and price in an afternoon. That does not mean the company has a production web data pipeline.

The difference appears when the scraper must run every morning, cover thousands of pages, reproduce the correct country or website state, recover from failures and deliver a dataset that other systems can trust. At that point, the build-versus-buy question is no longer about whether your team can extract data from HTML. It is about which parts of the collection system your organisation wants to own.

Continue Reading

Proxy management for web scraping: what actually matters

August 12, 2026

web scraping, residential proxies, Proxy management, proxy rotation, browser sessions
A scraper can have access to thousands of proxy IP addresses and still collect the wrong page, lose a stateful session or waste most of its budget on retries. The size of the proxy pool is rarely the main issue.

Proxy management is the process of coordinating network routes with session state, request rate, retries, geography and validation for each target website. Rotation is part of that process, but it is not the whole process.

The practical goal is not to make every request return 200 OK. It is to receive the expected page, extract valid records and complete the job at the required freshness and cost. That distinction changes how proxies should be selected, rotated and monitored.

Continue Reading

Scraping libraries vs web scraping platforms

August 11, 2026

web scraping infrastructure, Web Scraper Cloud, browser automation, Data engineering
A scraper can begin with three steps: request a page, parse its HTML and select a value. That may be the whole job once. When it must run every morning, process hundreds of thousands of URLs and deliver a validated dataset, extraction becomes only one part of a production system.

Libraries and platforms are often presented as code versus no-code. That is too simplistic. Libraries may handle HTTP, parsing or browser automation, while platforms can use visual builders, APIs or hosted code. The real choice is which parts of the operating stack your team wants to own.

Continue Reading

Empty pages, consent screens and bot challenges: telling them apart

August 10, 2026

Empty scraping results, web scraping troubleshooting, consent screen web scraping, empty page web scraping, bot challenge detection
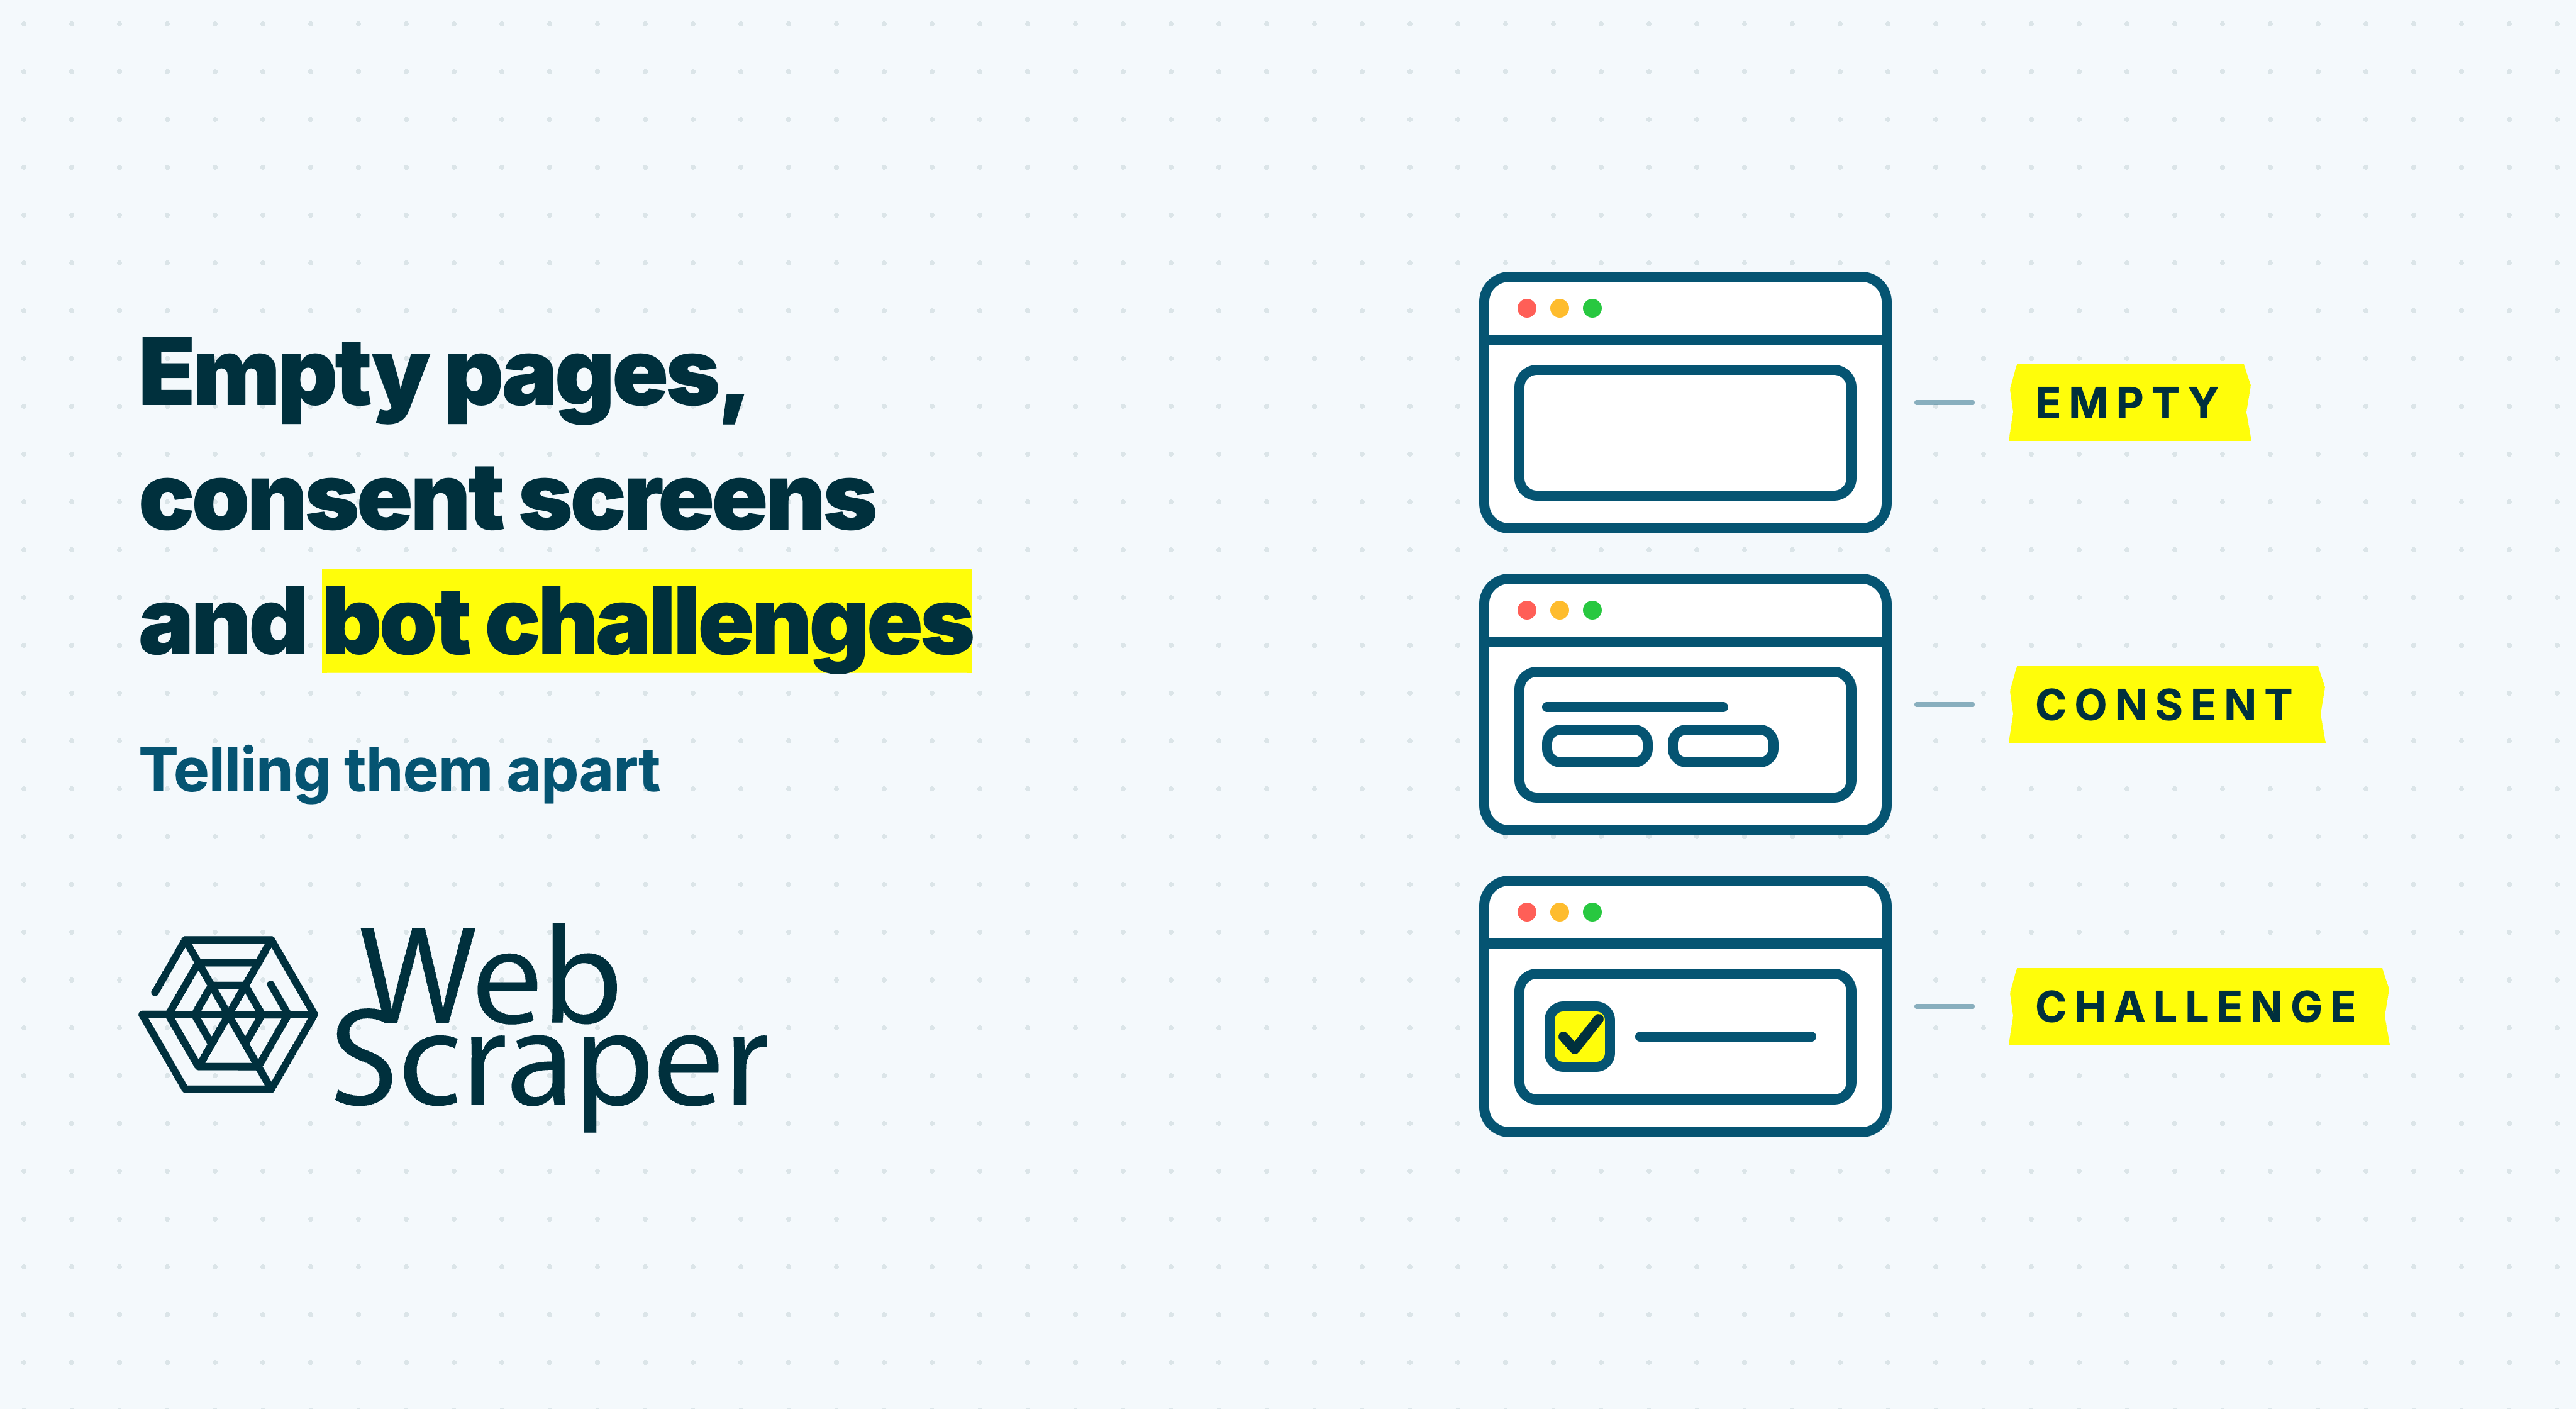
An empty scraping result does not necessarily mean that the browser received an empty page. The requested page may legitimately contain no records, the expected content may still be loading, a consent state may withhold it, a bot challenge may have replaced it or the configured selectors may not match it. In Web Scraper Cloud, an empty page means that the page loaded successfully but the configured selectors extracted no data.

In short: Similar screenshots can require entirely different fixes. Check the response, the rendered page and one controlled transition. The decisive question is not what the screenshot resembles, but what evidence explains the missing data.

Continue Reading

8 best web scraping browser extensions in 2026

August 10, 2026

data extraction, Firefox extension, no-code scraping, web scraping, Chrome extension, browser extension
A web scraping browser extension can turn a page you are already viewing into a structured dataset without requiring Python, a command line or a separate desktop application.

Some extensions capture a clean table in one click. Others build reusable, multi-level workflows or configure scrapers that later run in the cloud. The right choice depends on whether you need speed, control, reusability or unattended execution.

Continue Reading

Web crawling vs web scraping vs data extraction

August 09, 2026

data extraction, data pipelines, web crawler, web data, scraping workflows, Data collection
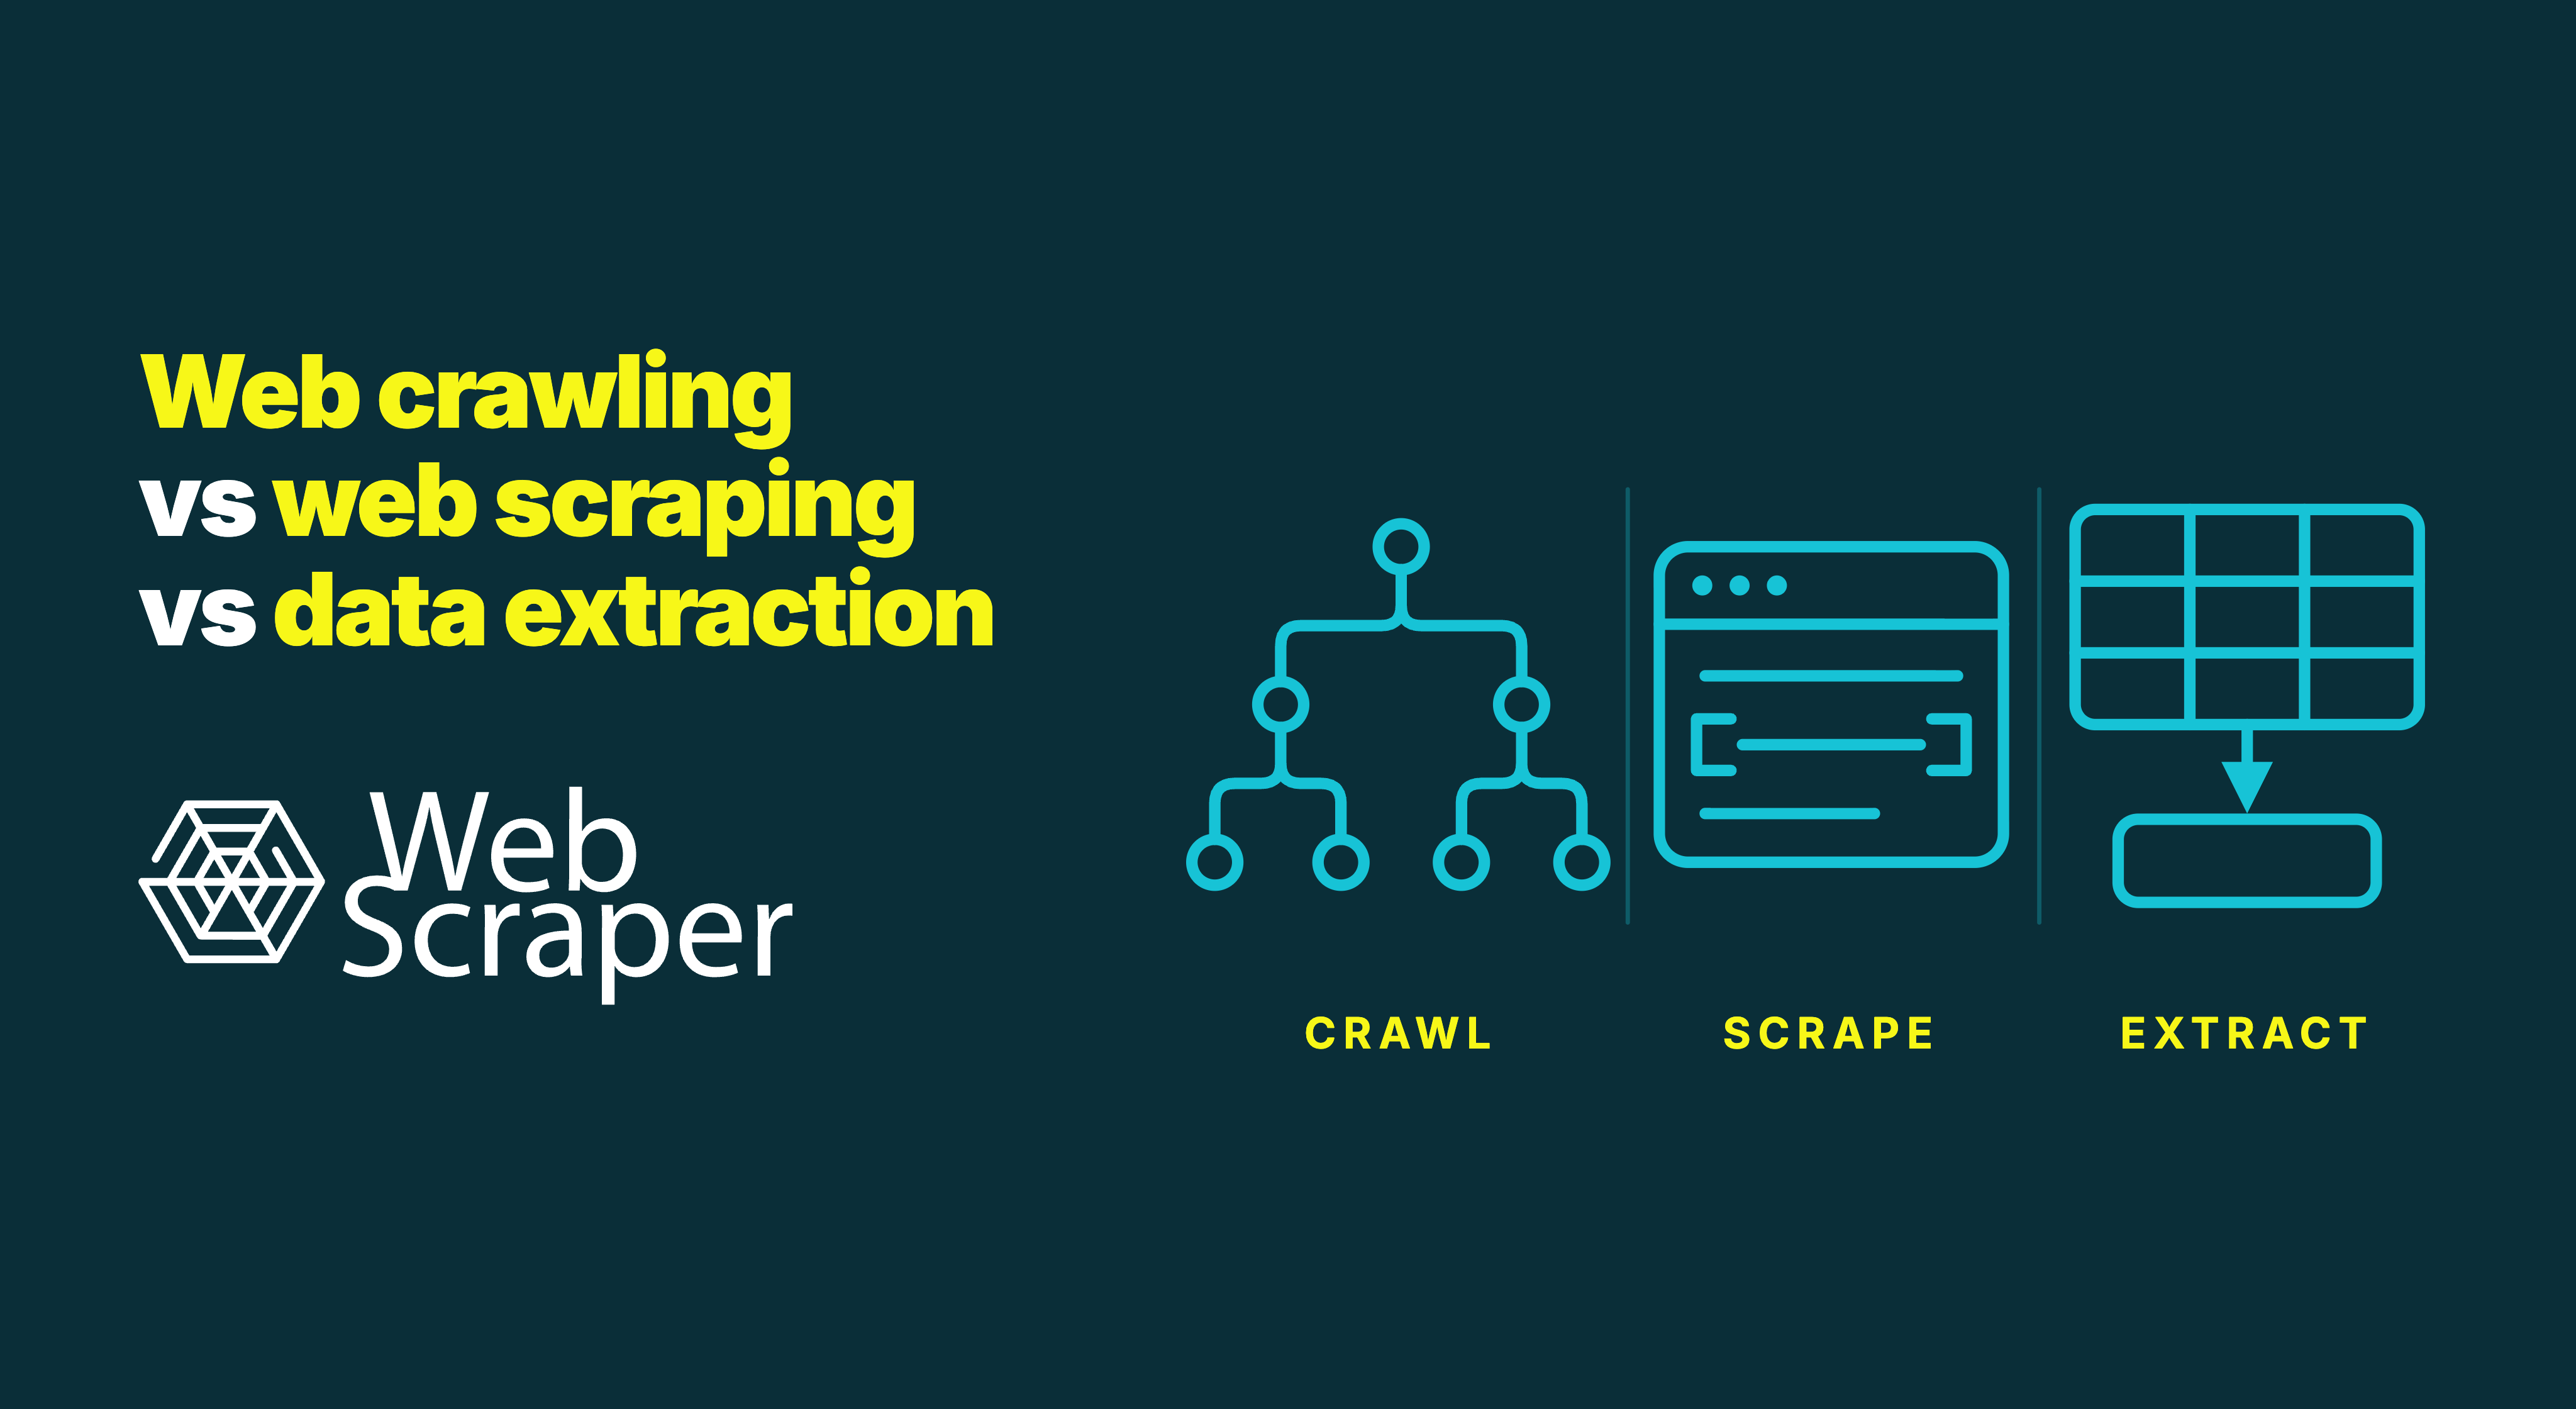
Web crawling discovers and schedules pages. Web scraping collects content or data from websites. Data extraction selects the required values from a source and maps them into fields or records.

The boundaries are useful, but the terms are not three universally standardised steps. In practice, web scraping often names the complete workflow, including discovery, retrieval, browser interactions and extraction.

The distinction matters when something goes wrong. A project can reach every intended URL but extract the wrong price. It can also extract perfect records from only 60 per cent of the intended pages. Both jobs may report that they finished, but they have different failures.

Continue Reading

How JavaScript-rendered content affects web scraping

August 08, 2026

headless browsers, lazy loading, Web Scraper Cloud, browser automation, JavaScript, client-side rendering, infinite scroll, dynamic content
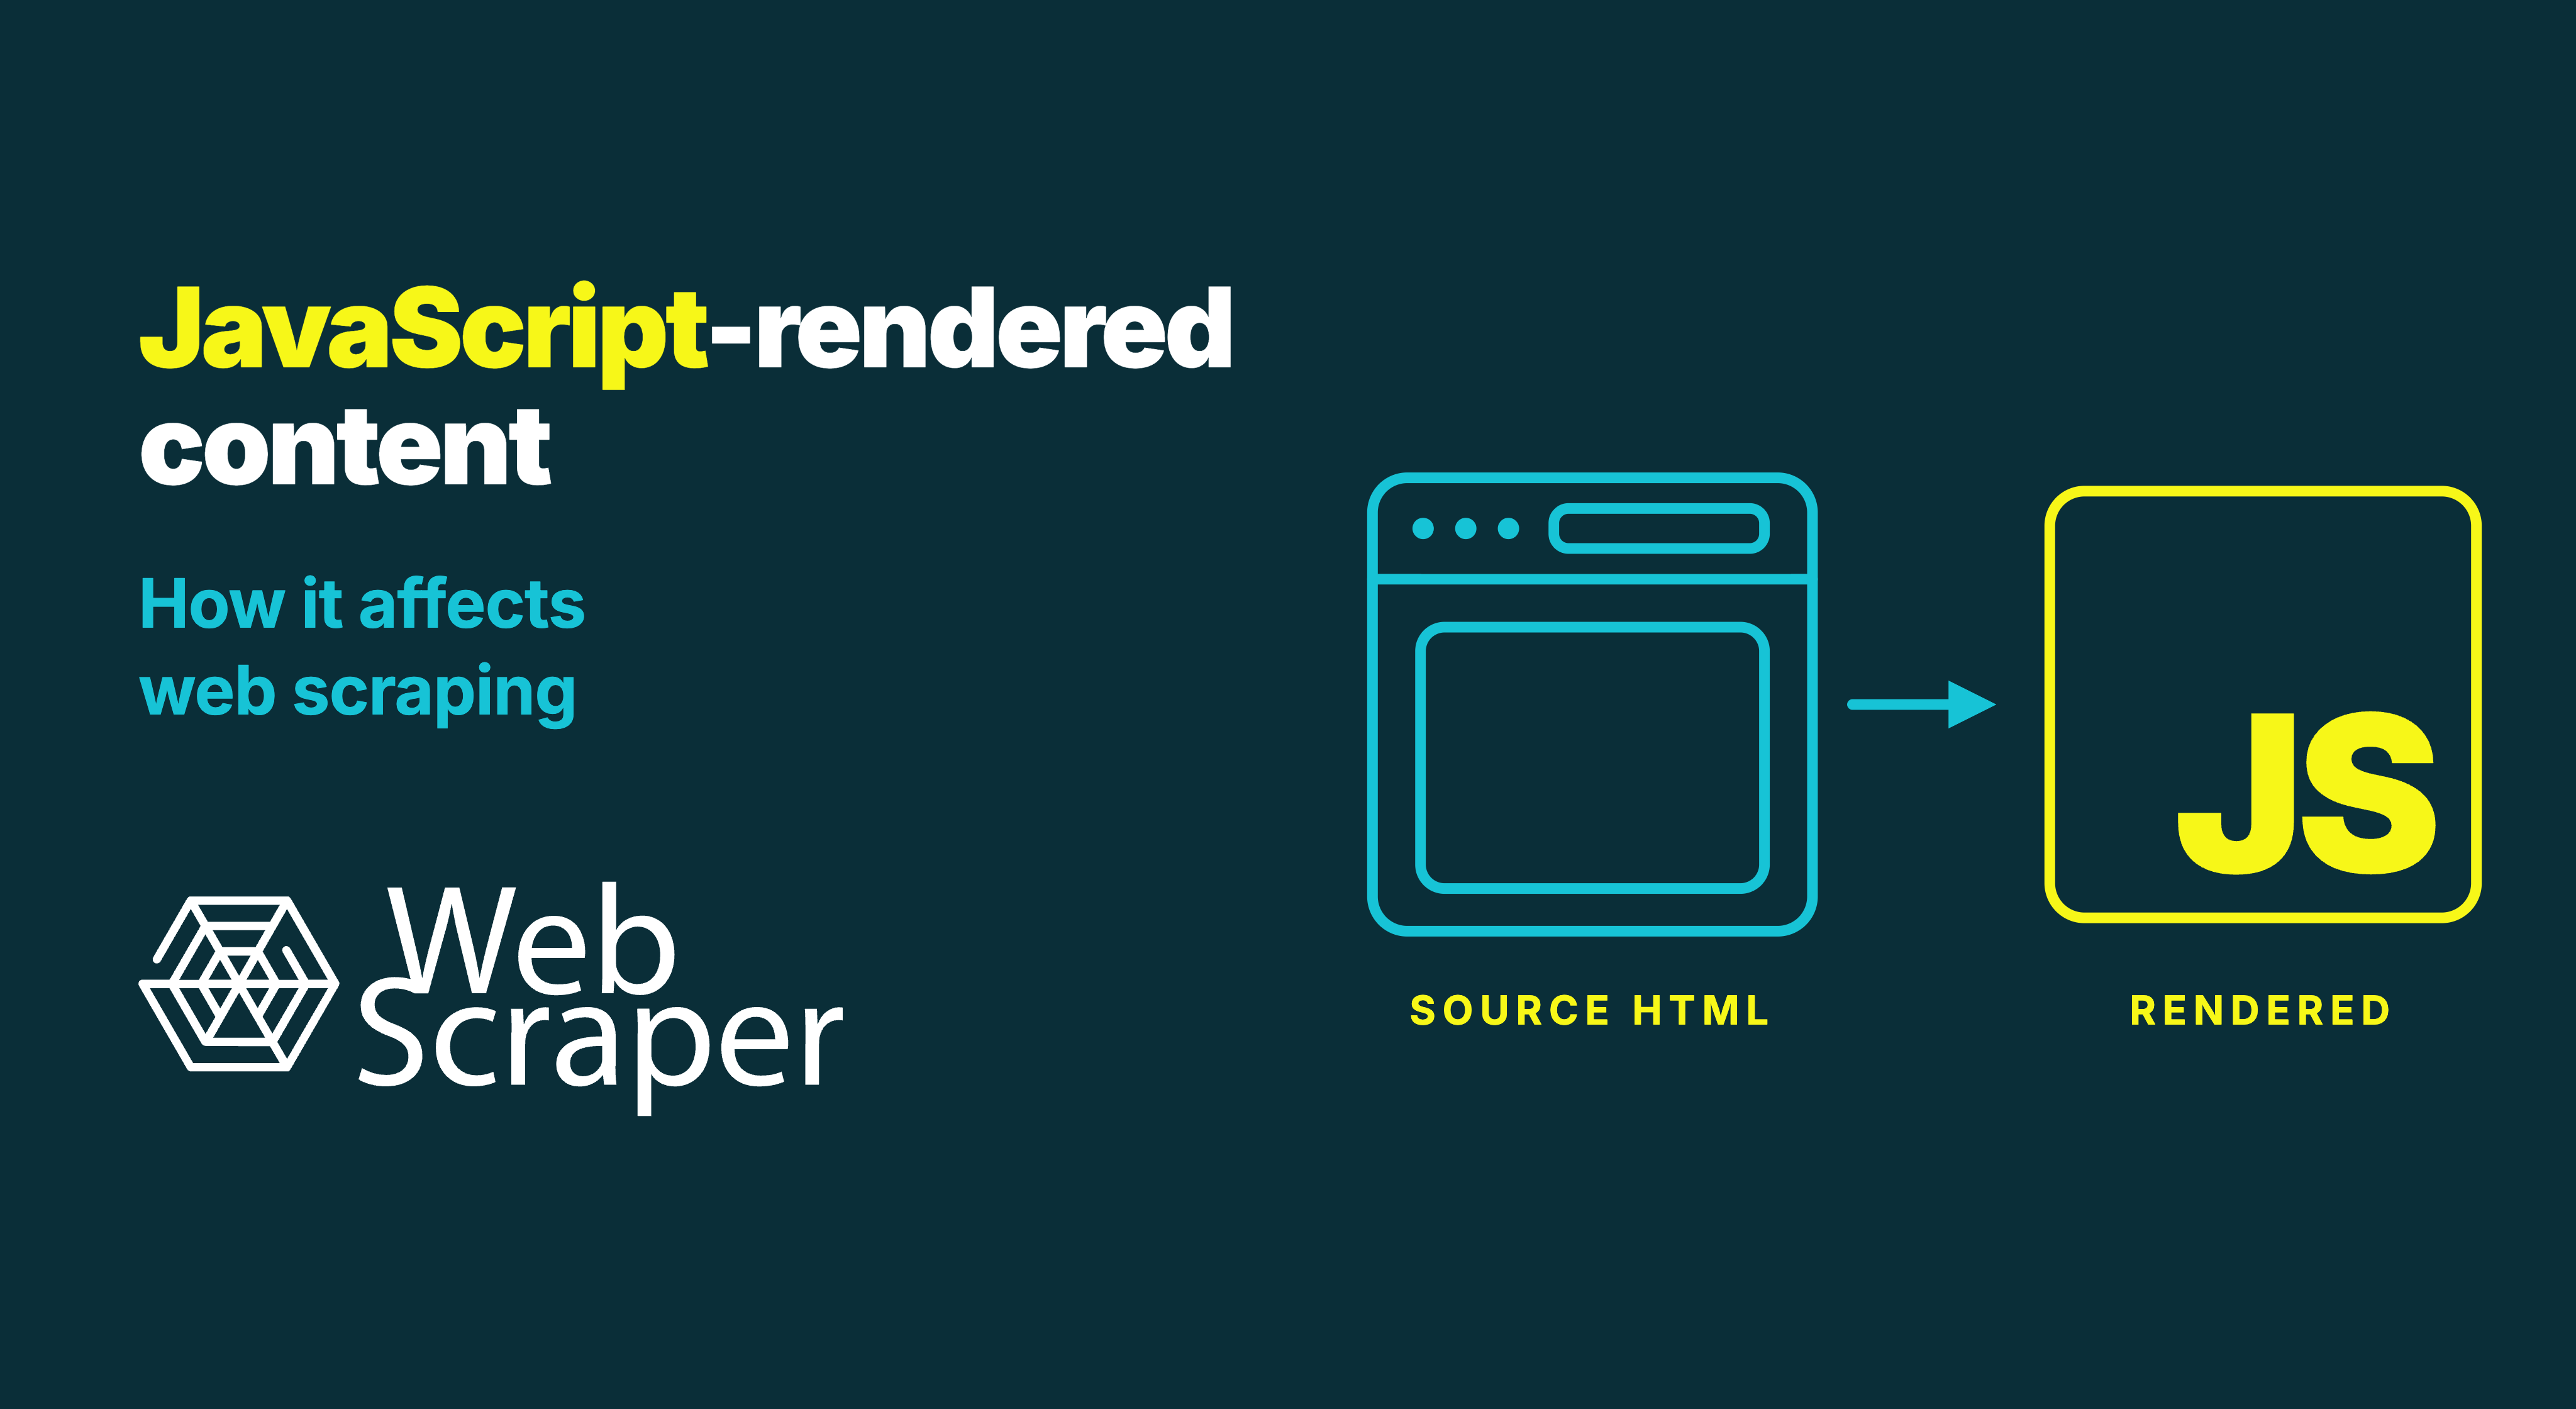
A product price is visible in your browser. The page loads normally, the product is in stock and the value is clearly displayed. Yet a scraper requests the same URL and returns an empty price field - or no product record at all.

The scraper may not be looking at the same version of the page.

A website can return an initial HTML document, execute JavaScript, request more data and update the page without another full navigation. It may then change the data again when someone scrolls, clicks a button, selects a variation or opens a tab.

JavaScript-rendered content therefore affects more than page-loading time. It changes where the required data exists, when it becomes available and which actions are needed to produce it. Reliable JavaScript web scraping depends on reaching the correct page state, not simply enabling JavaScript and waiting for the page to “load”.

Continue Reading

Web Scraping vs AI Scraping: Which should you use?

August 05, 2026

data extraction, Web scraping automation, AI scraping, agentic scraping, web scraping, rule-based scraping, LLM data extraction

AI scraping promises a simple workflow: describe the data you want, provide a website and let a model work out the rest. Rule-based scraping is less glamorous, but it gives you explicit navigation and extraction logic that can be inspected and repeated.

The useful choice is not old automation versus intelligent automation. Use rule-based scraping for stable, repeated collection where exact output matters; use AI scraping when layouts, meaning or discovery paths vary; and combine them when production reliability and flexibility are both required.

Continue Reading