Blog

Web scraping software vs managed scraping service

August 28, 2026

data operations, web data, managed scraping service, scraping platforms
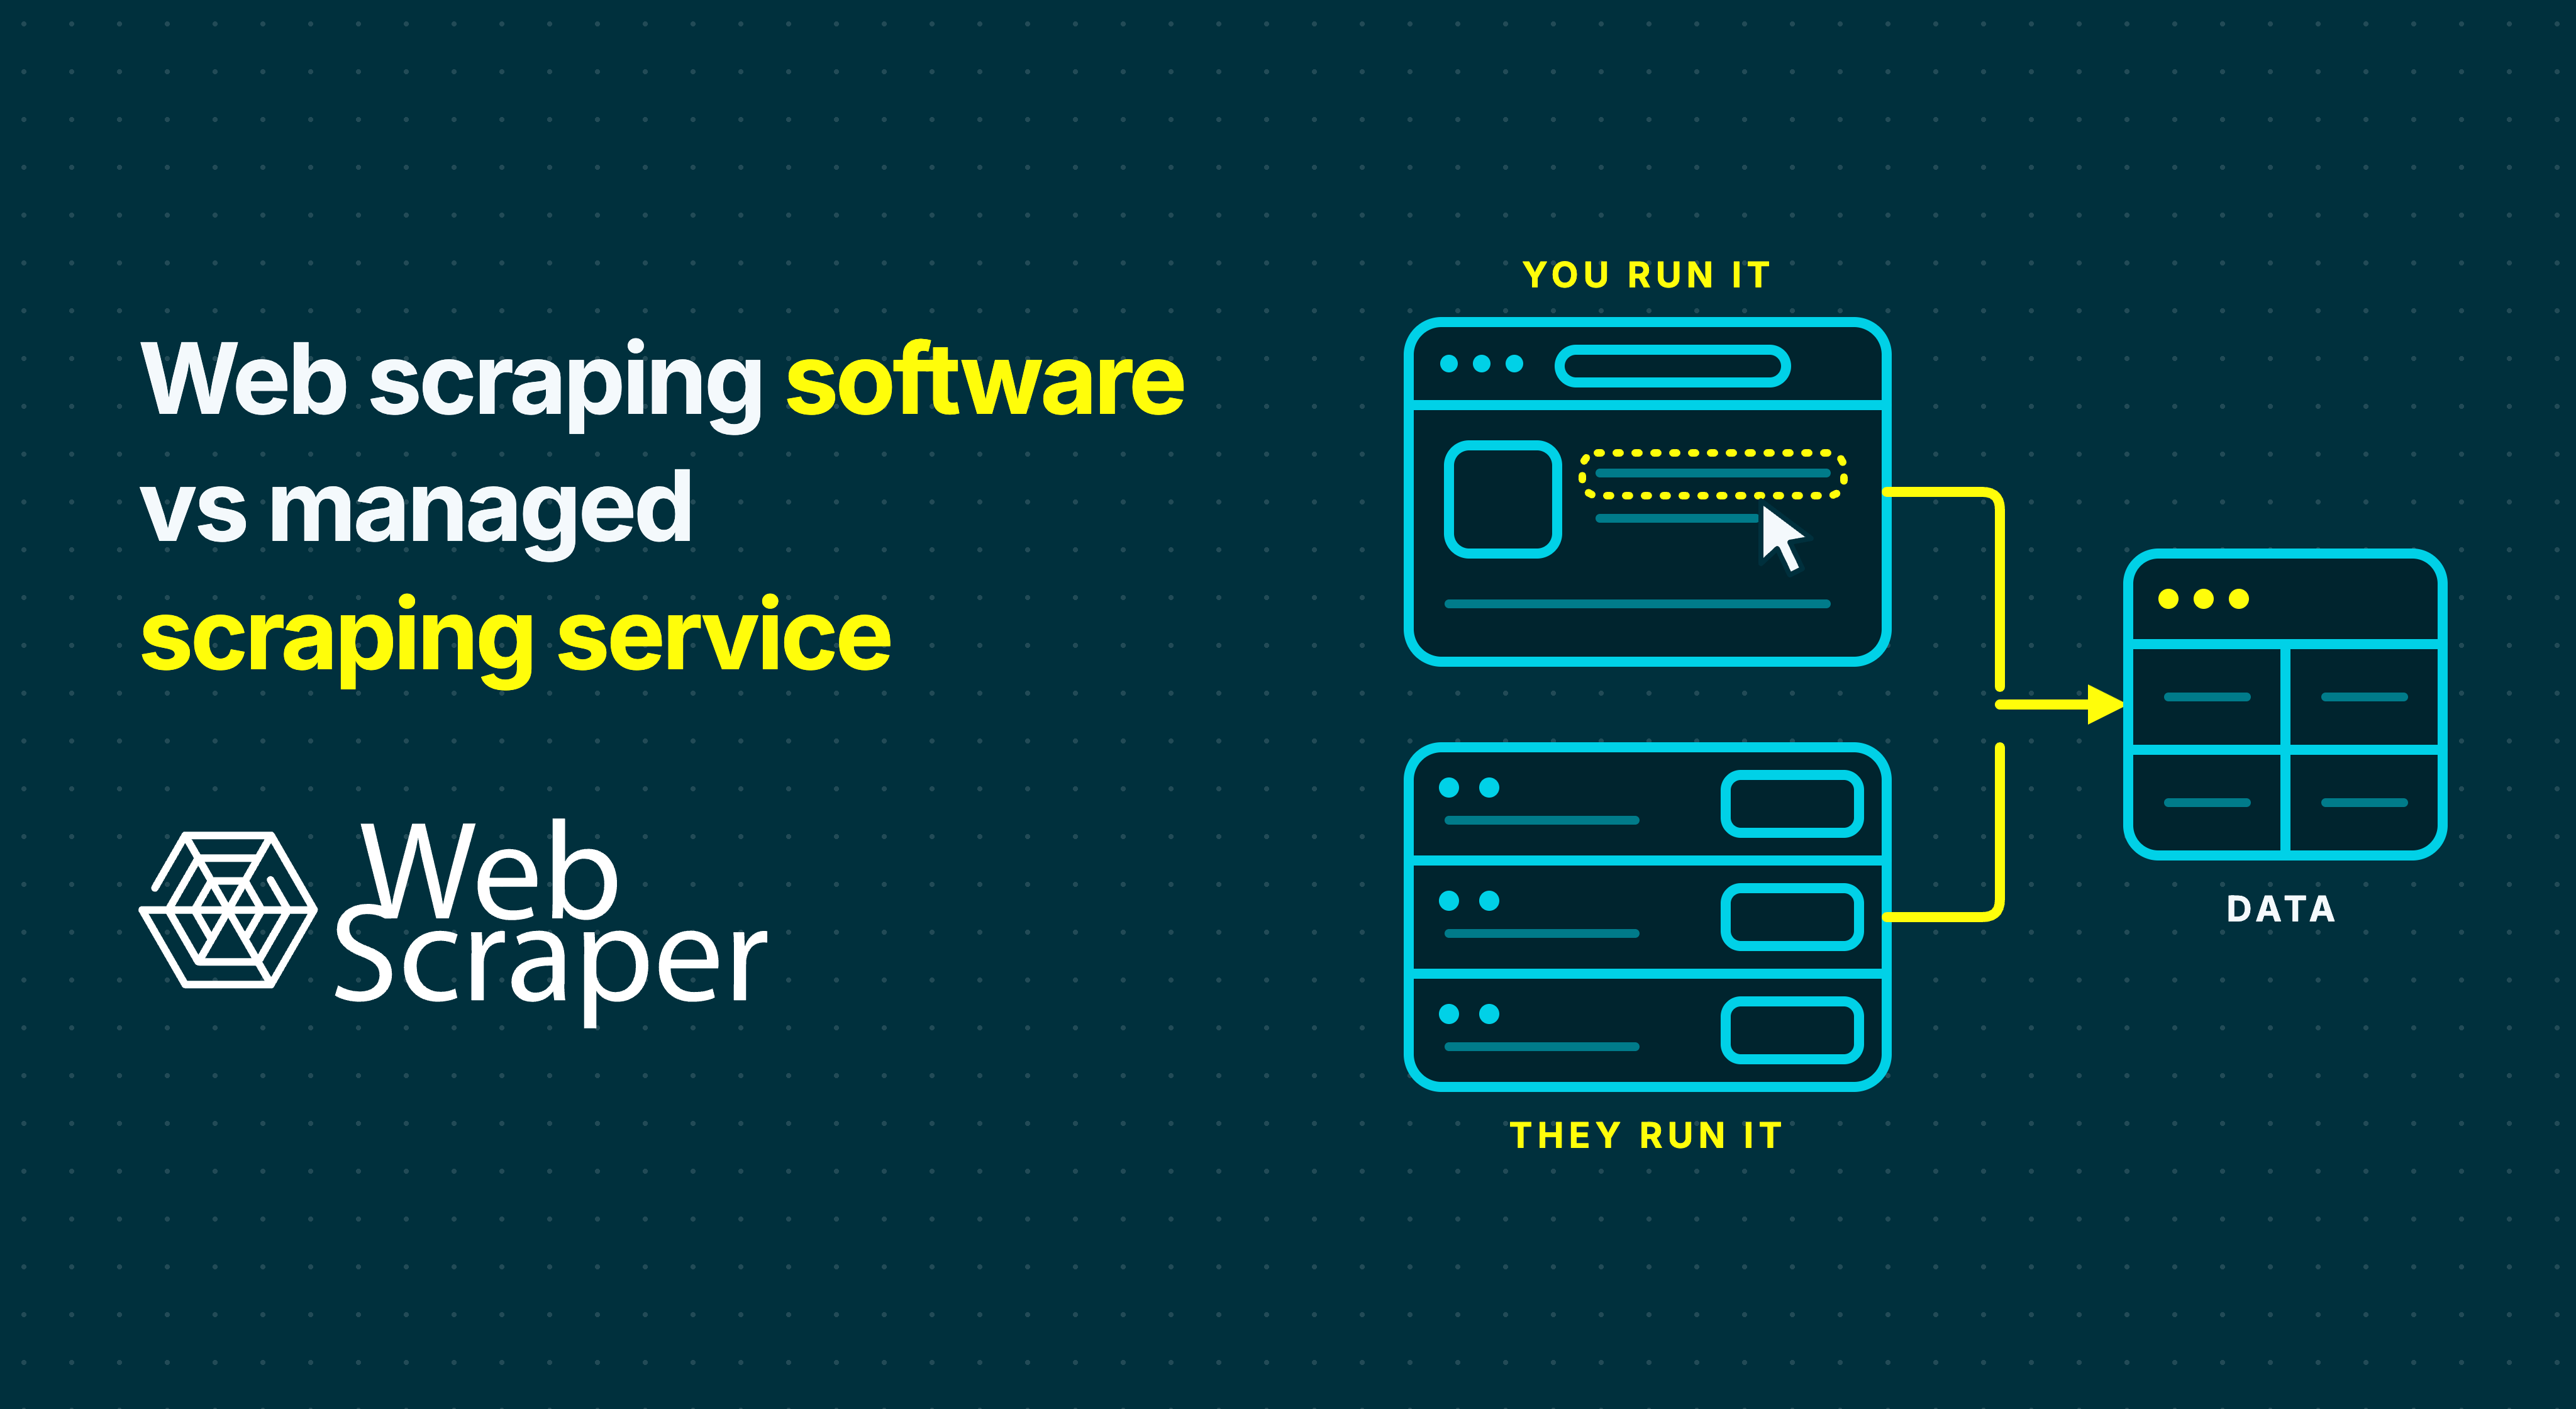
Web scraping software gives your team direct control over how a dataset is collected and maintained. A managed scraping service takes on more of the target-specific work and delivers data against an agreed scope.

For recurring public data, self-service software is often the stronger starting point when someone can own the scraper. Choose a managed service when the real requirement is to outsource configuration, repairs, quality assurance and delivery, not simply to run scraping jobs in the cloud.

Continue Reading

Browser fingerprinting and bot detection explained

August 27, 2026

bot detection, Browser fingerprinting, Scraper troubleshooting
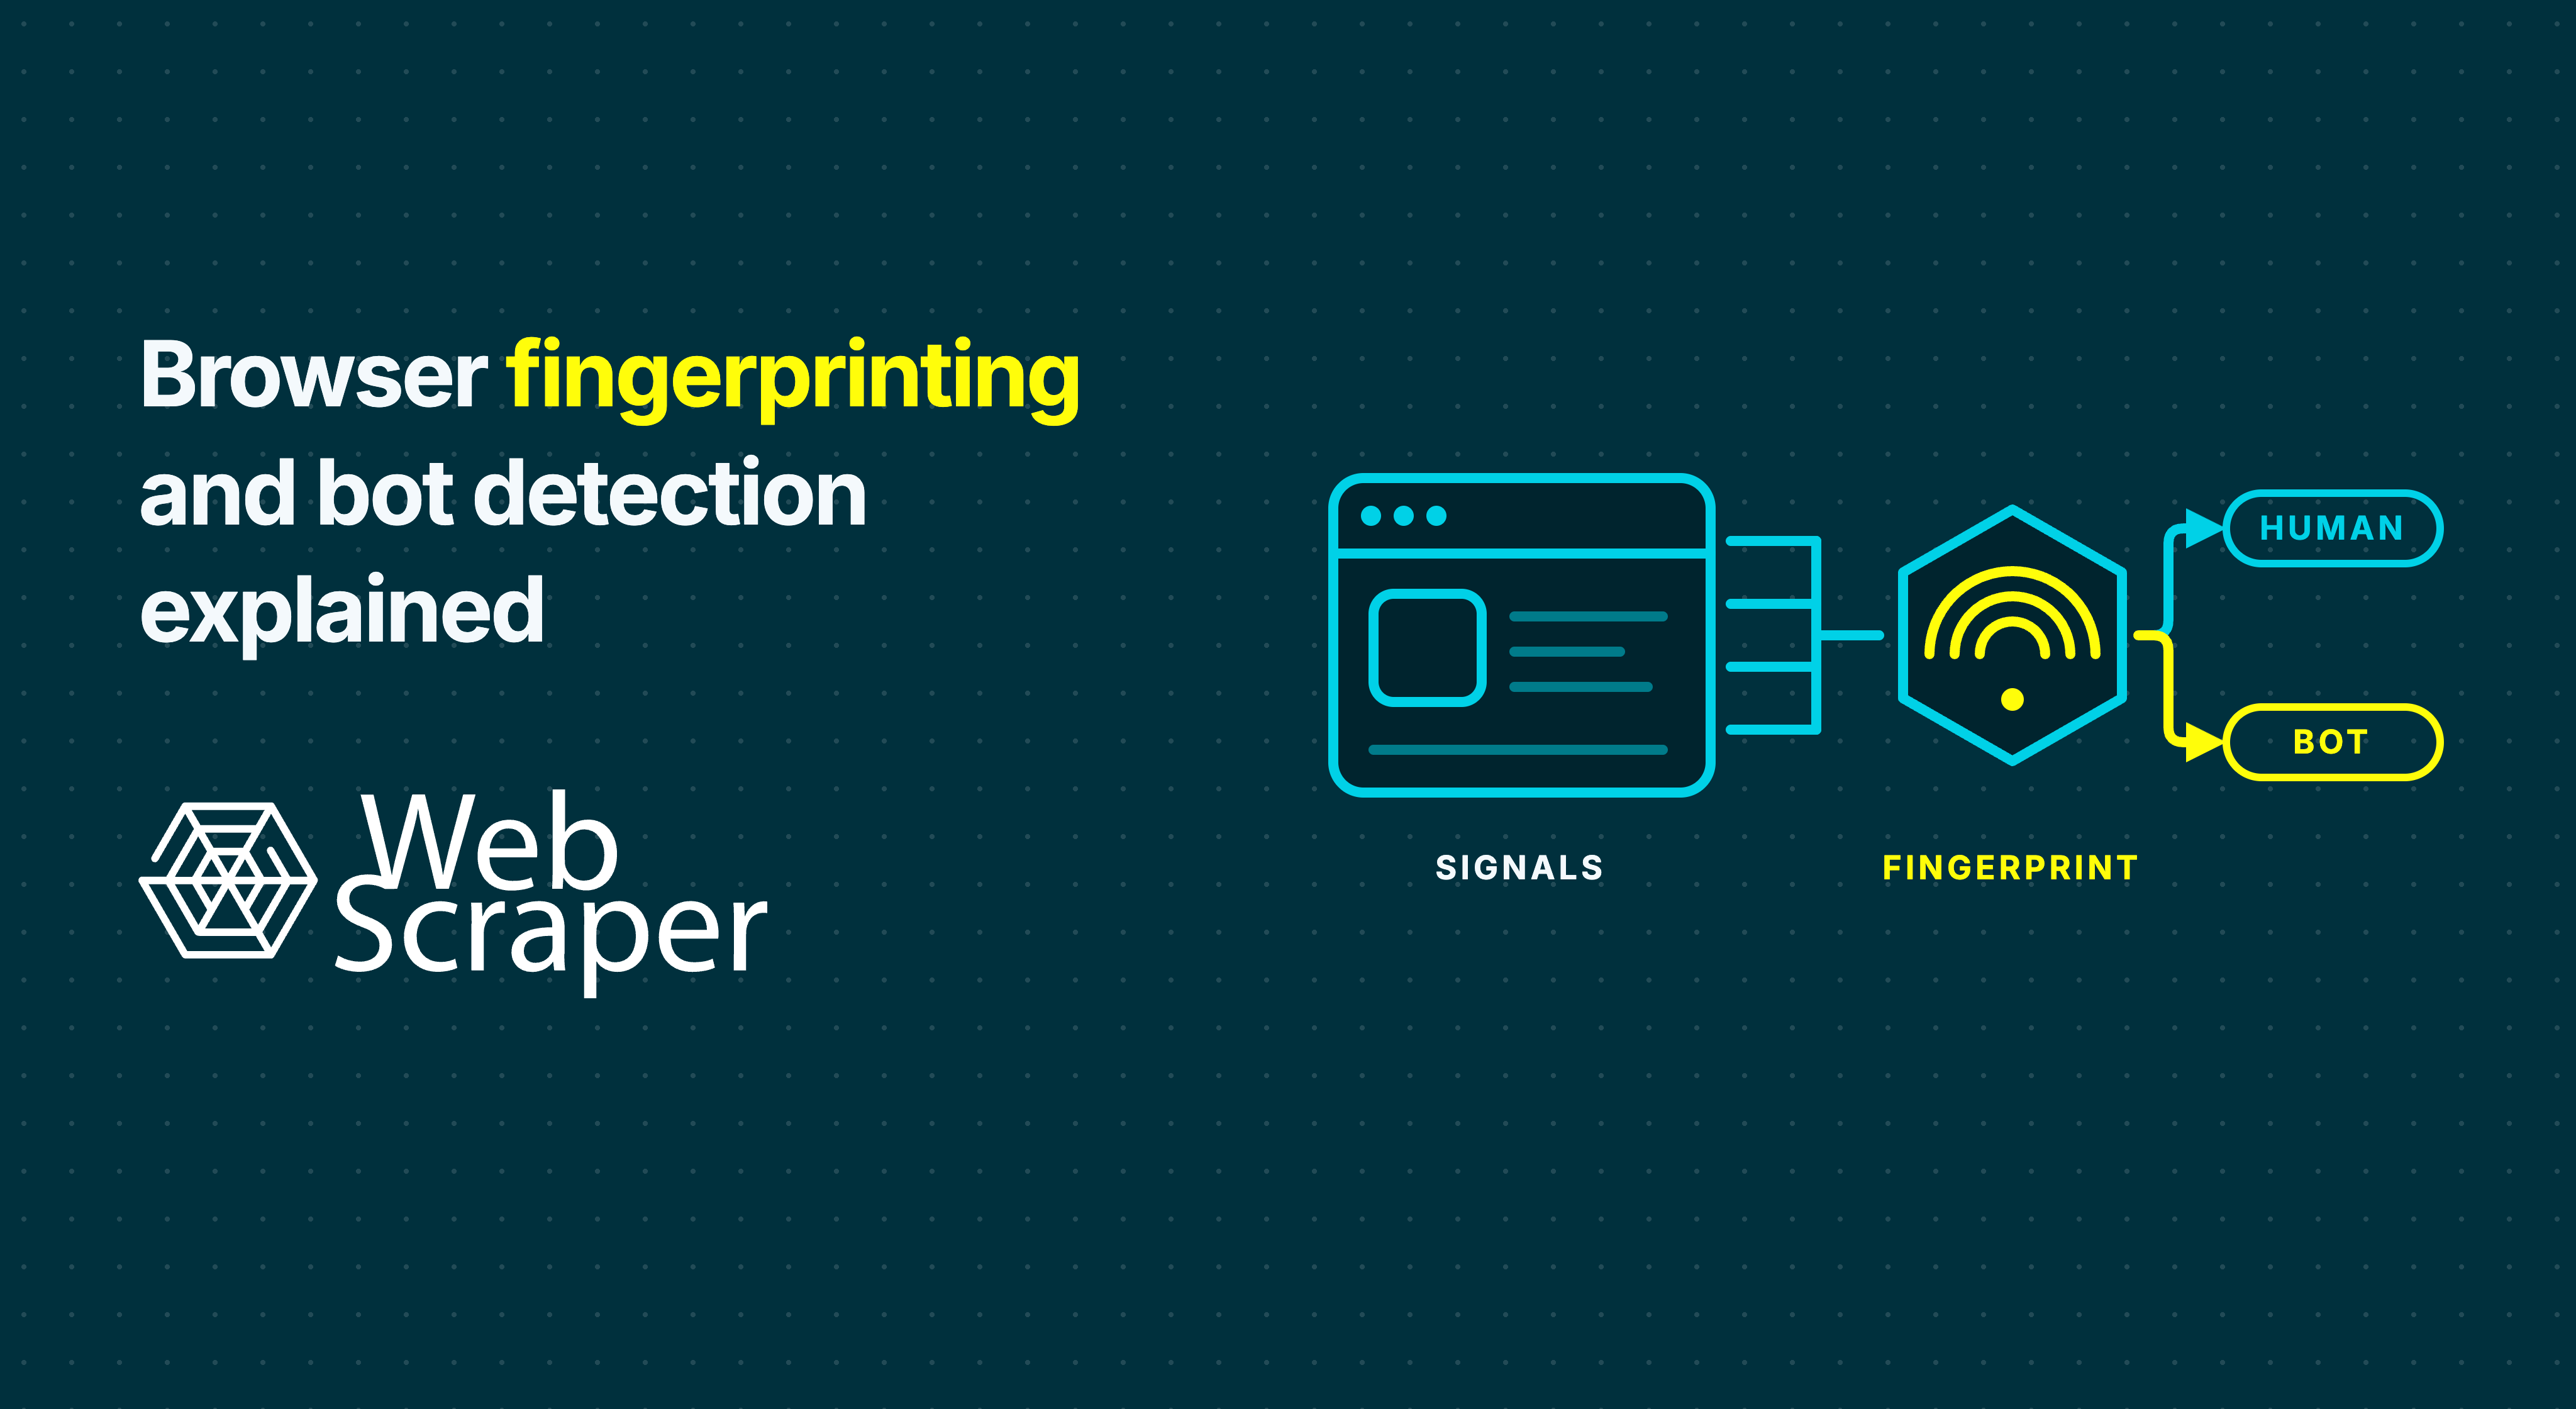
Browser fingerprinting lets a website observe and combine characteristics of a request, browser, device and session. In bot detection, those characteristics are usually evidence within a wider classification process, not one magic identifier.

That is why changing an IP address or user-agent string may not fix a blocked scraper. The transport, JavaScript environment, automation state, session history or request behaviour can still look automated, and a successful response can still contain the wrong page.

Continue Reading

Web Scraper vs Simplescraper

August 27, 2026

web scraper, data extraction, web scraping, Comparison

Simplescraper is the quicker choice when you want to detect a clear list, extract it with minimal configuration and send the result to an API or no-code integration. Web Scraper is the stronger overall choice for recurring commercial datasets that span pagination and detail pages, require explicit validation or need economical Cloud execution at scale.

Both combine browser-based setup with Cloud automation. The important difference is what happens after the first successful scrape: how the workflow is maintained, how incomplete output is detected and how much it costs as volume grows.

Continue Reading

Web Scraper vs Data Miner

August 27, 2026

Data extraction tool, web scraping tools, web scraping, Comparison
Web Scraper and Data Miner are both no-code browser scraping tools, but they suit different jobs. Data Miner can be quicker when a current recipe fits a small browser-run task. Web Scraper is stronger when the extraction must become a reusable, validated dataset that combines multiple page types and later runs remotely on a schedule. Here, Data Miner refers to the product, not the separate discipline of analytical data mining.

Continue Reading

Free web scraper vs paid web scraper: when to pay

August 26, 2026

Web Scraper extension, Web Scraper Cloud, web scraping
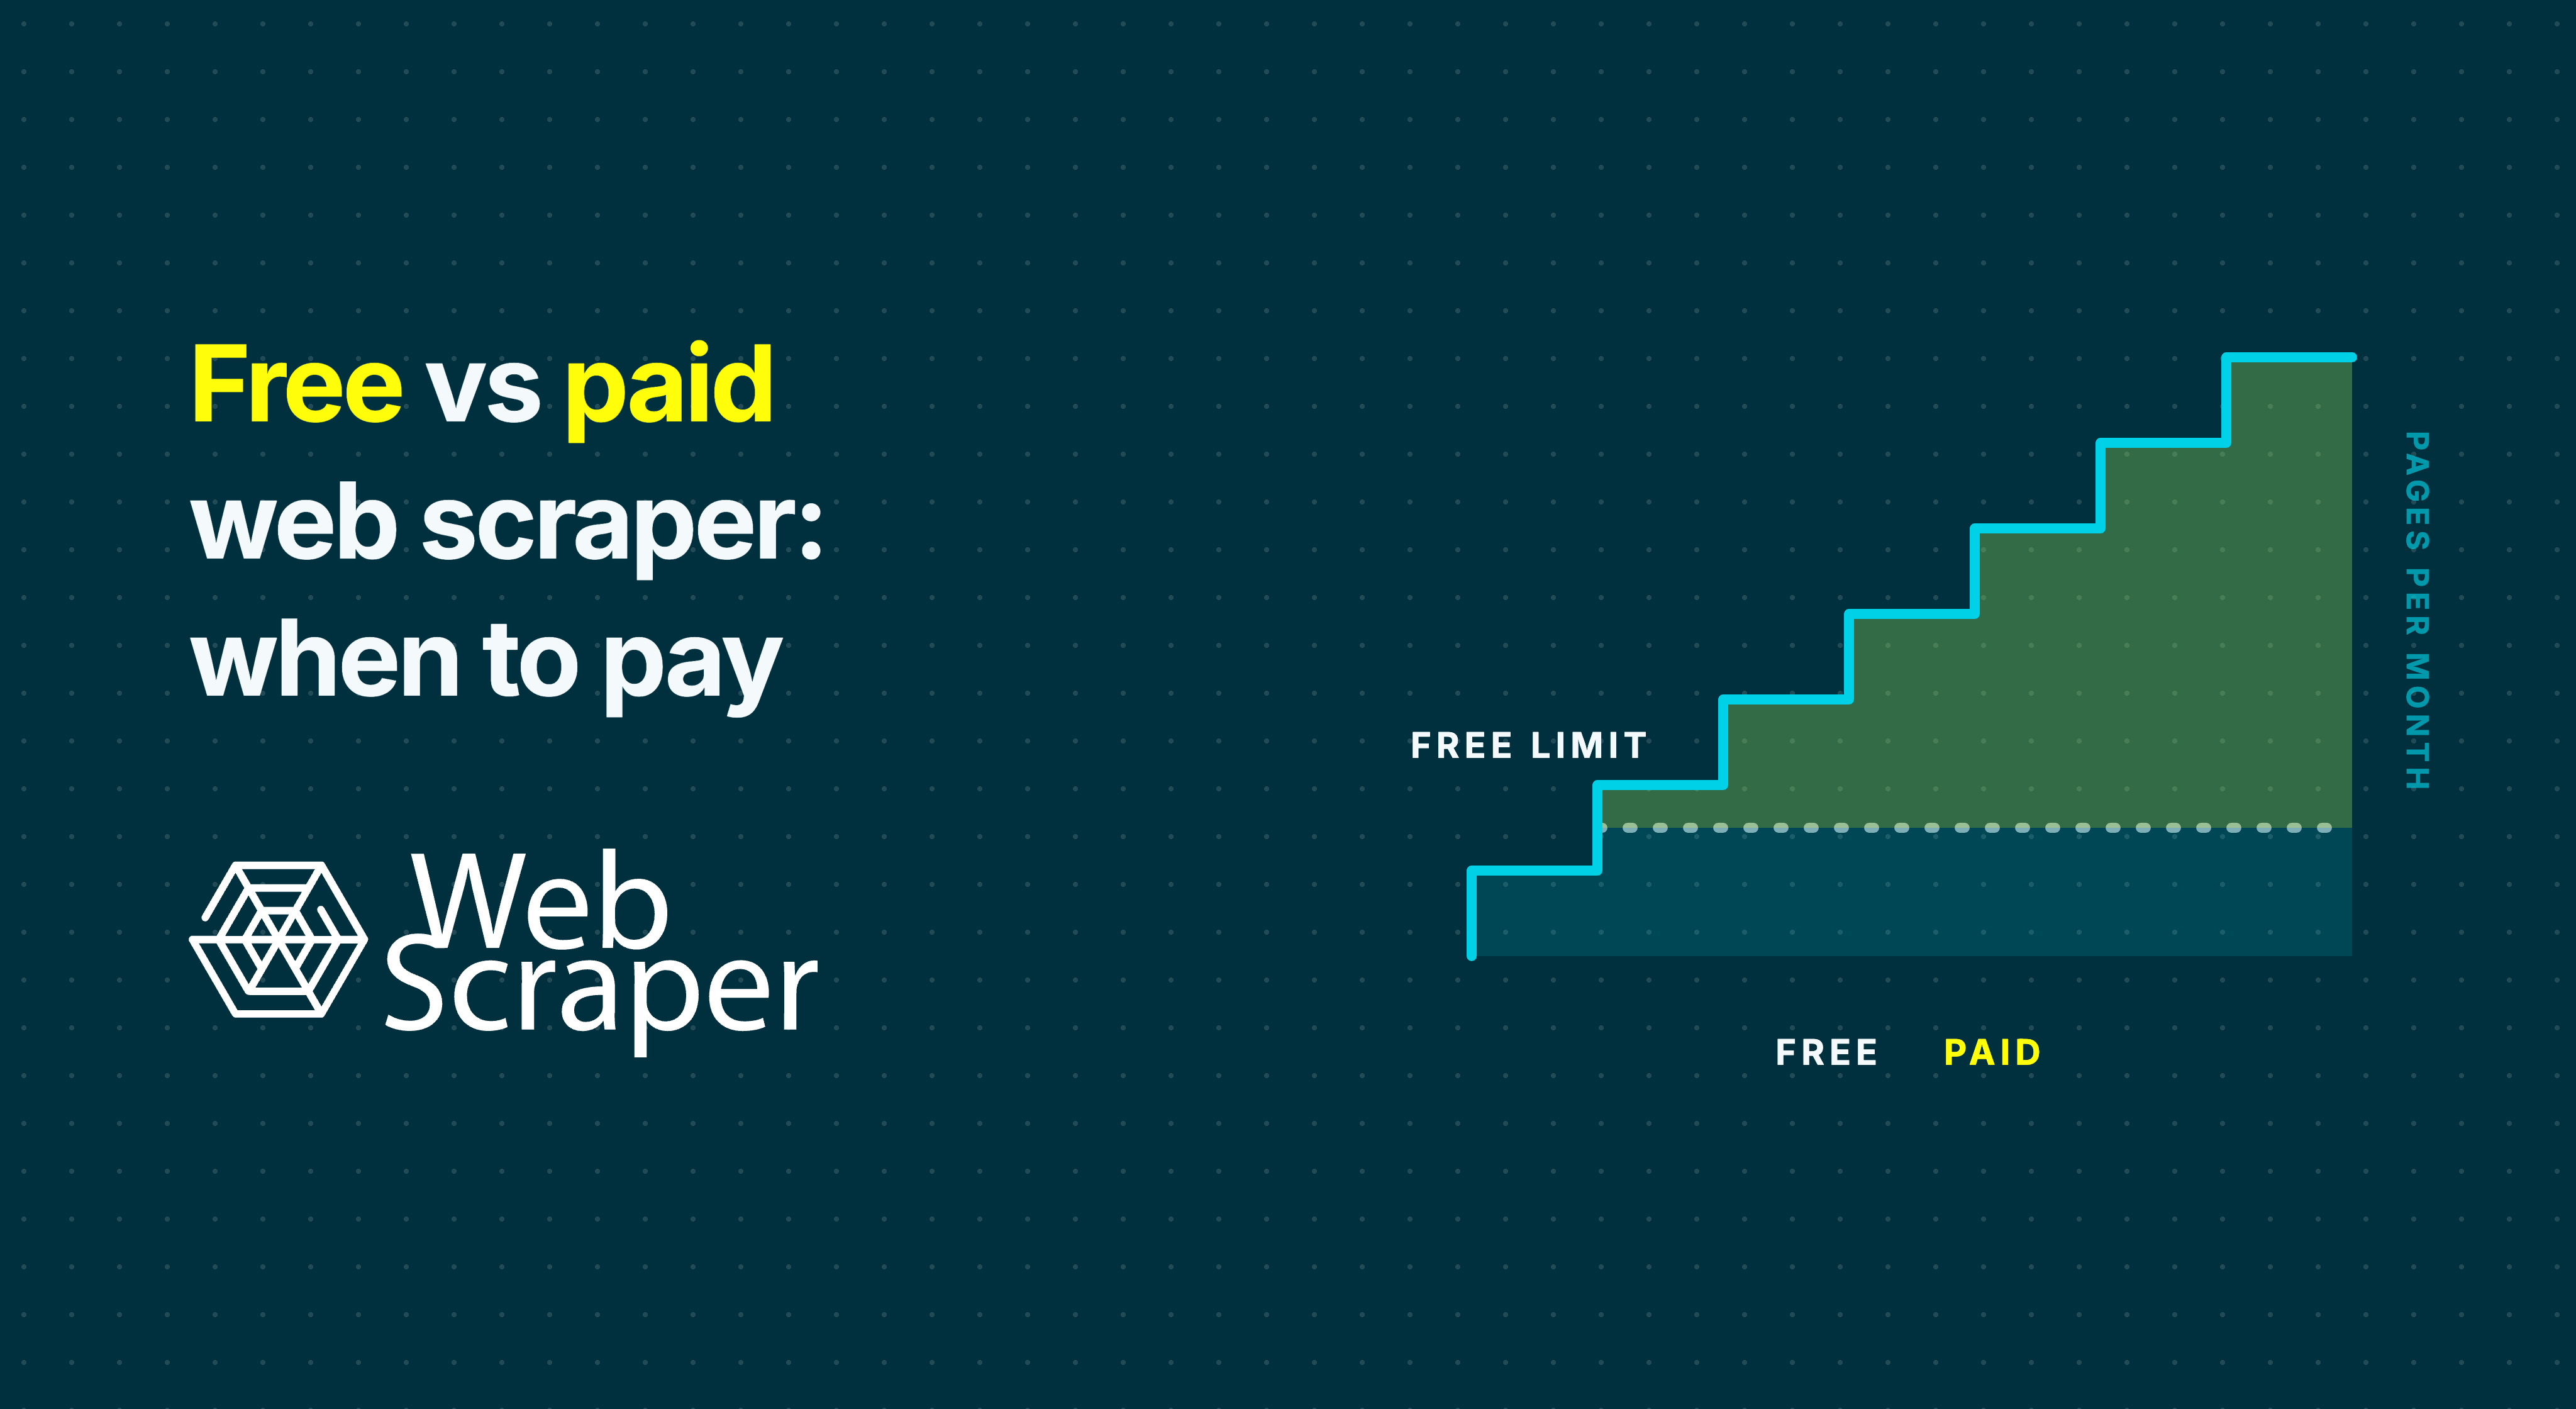
Use a free web scraper for occasional, supervised jobs. Pay for managed execution when the same dataset must run on schedule, recover from failures or reach another system without manual work.

Continue Reading

Visual web scraper vs Python script

August 26, 2026

Scripts, Web Scraper Cloud, Visual scrapers, web scraping, Python
A visual web scraper is usually the better starting point when a business needs a repeatable dataset that analysts, operations staff and developers can all inspect. A Python script is stronger when the workflow needs arbitrary logic, deep application integration or complete control over the runtime.

Both approaches can extract one value from one page. The better choice is the one your team can validate, repair and operate after pagination, JavaScript, layout changes and recurring execution are added.

Continue Reading

Web scraping project cost: a practical estimate

August 26, 2026

Web Scraper Cloud, Proxy management, Scraping infrastructure
A useful web scraping project cost estimate is not the price of a scraper, server or subscription. It is the total cost of delivering data that meets your coverage, quality and freshness requirements.

The practical method is to define the accepted output, measure a representative pilot and calculate total cost per accepted record or dataset. This exposes retries, validation, maintenance and operating labour that a price-per-page comparison can miss.

Continue Reading

Do you need a proxy for web scraping?

August 25, 2026

web scraping, Proxy management, proxy rotation, proxy
No, not every web scraping job needs a proxy. A small test or occasional collection from accessible public pages may work reliably from your normal connection. Add a proxy when evidence shows that the source IP, network type or location is causing failures, or when repeatable automation would otherwise depend on one route.

Usually, test directly first, use a datacenter proxy when routine automation needs another route, and test residential routing only when controlled results justify the extra cost and complexity.

Continue Reading

Browser automation vs HTTP scraping: how to choose

August 25, 2026

HTTP, browser automation

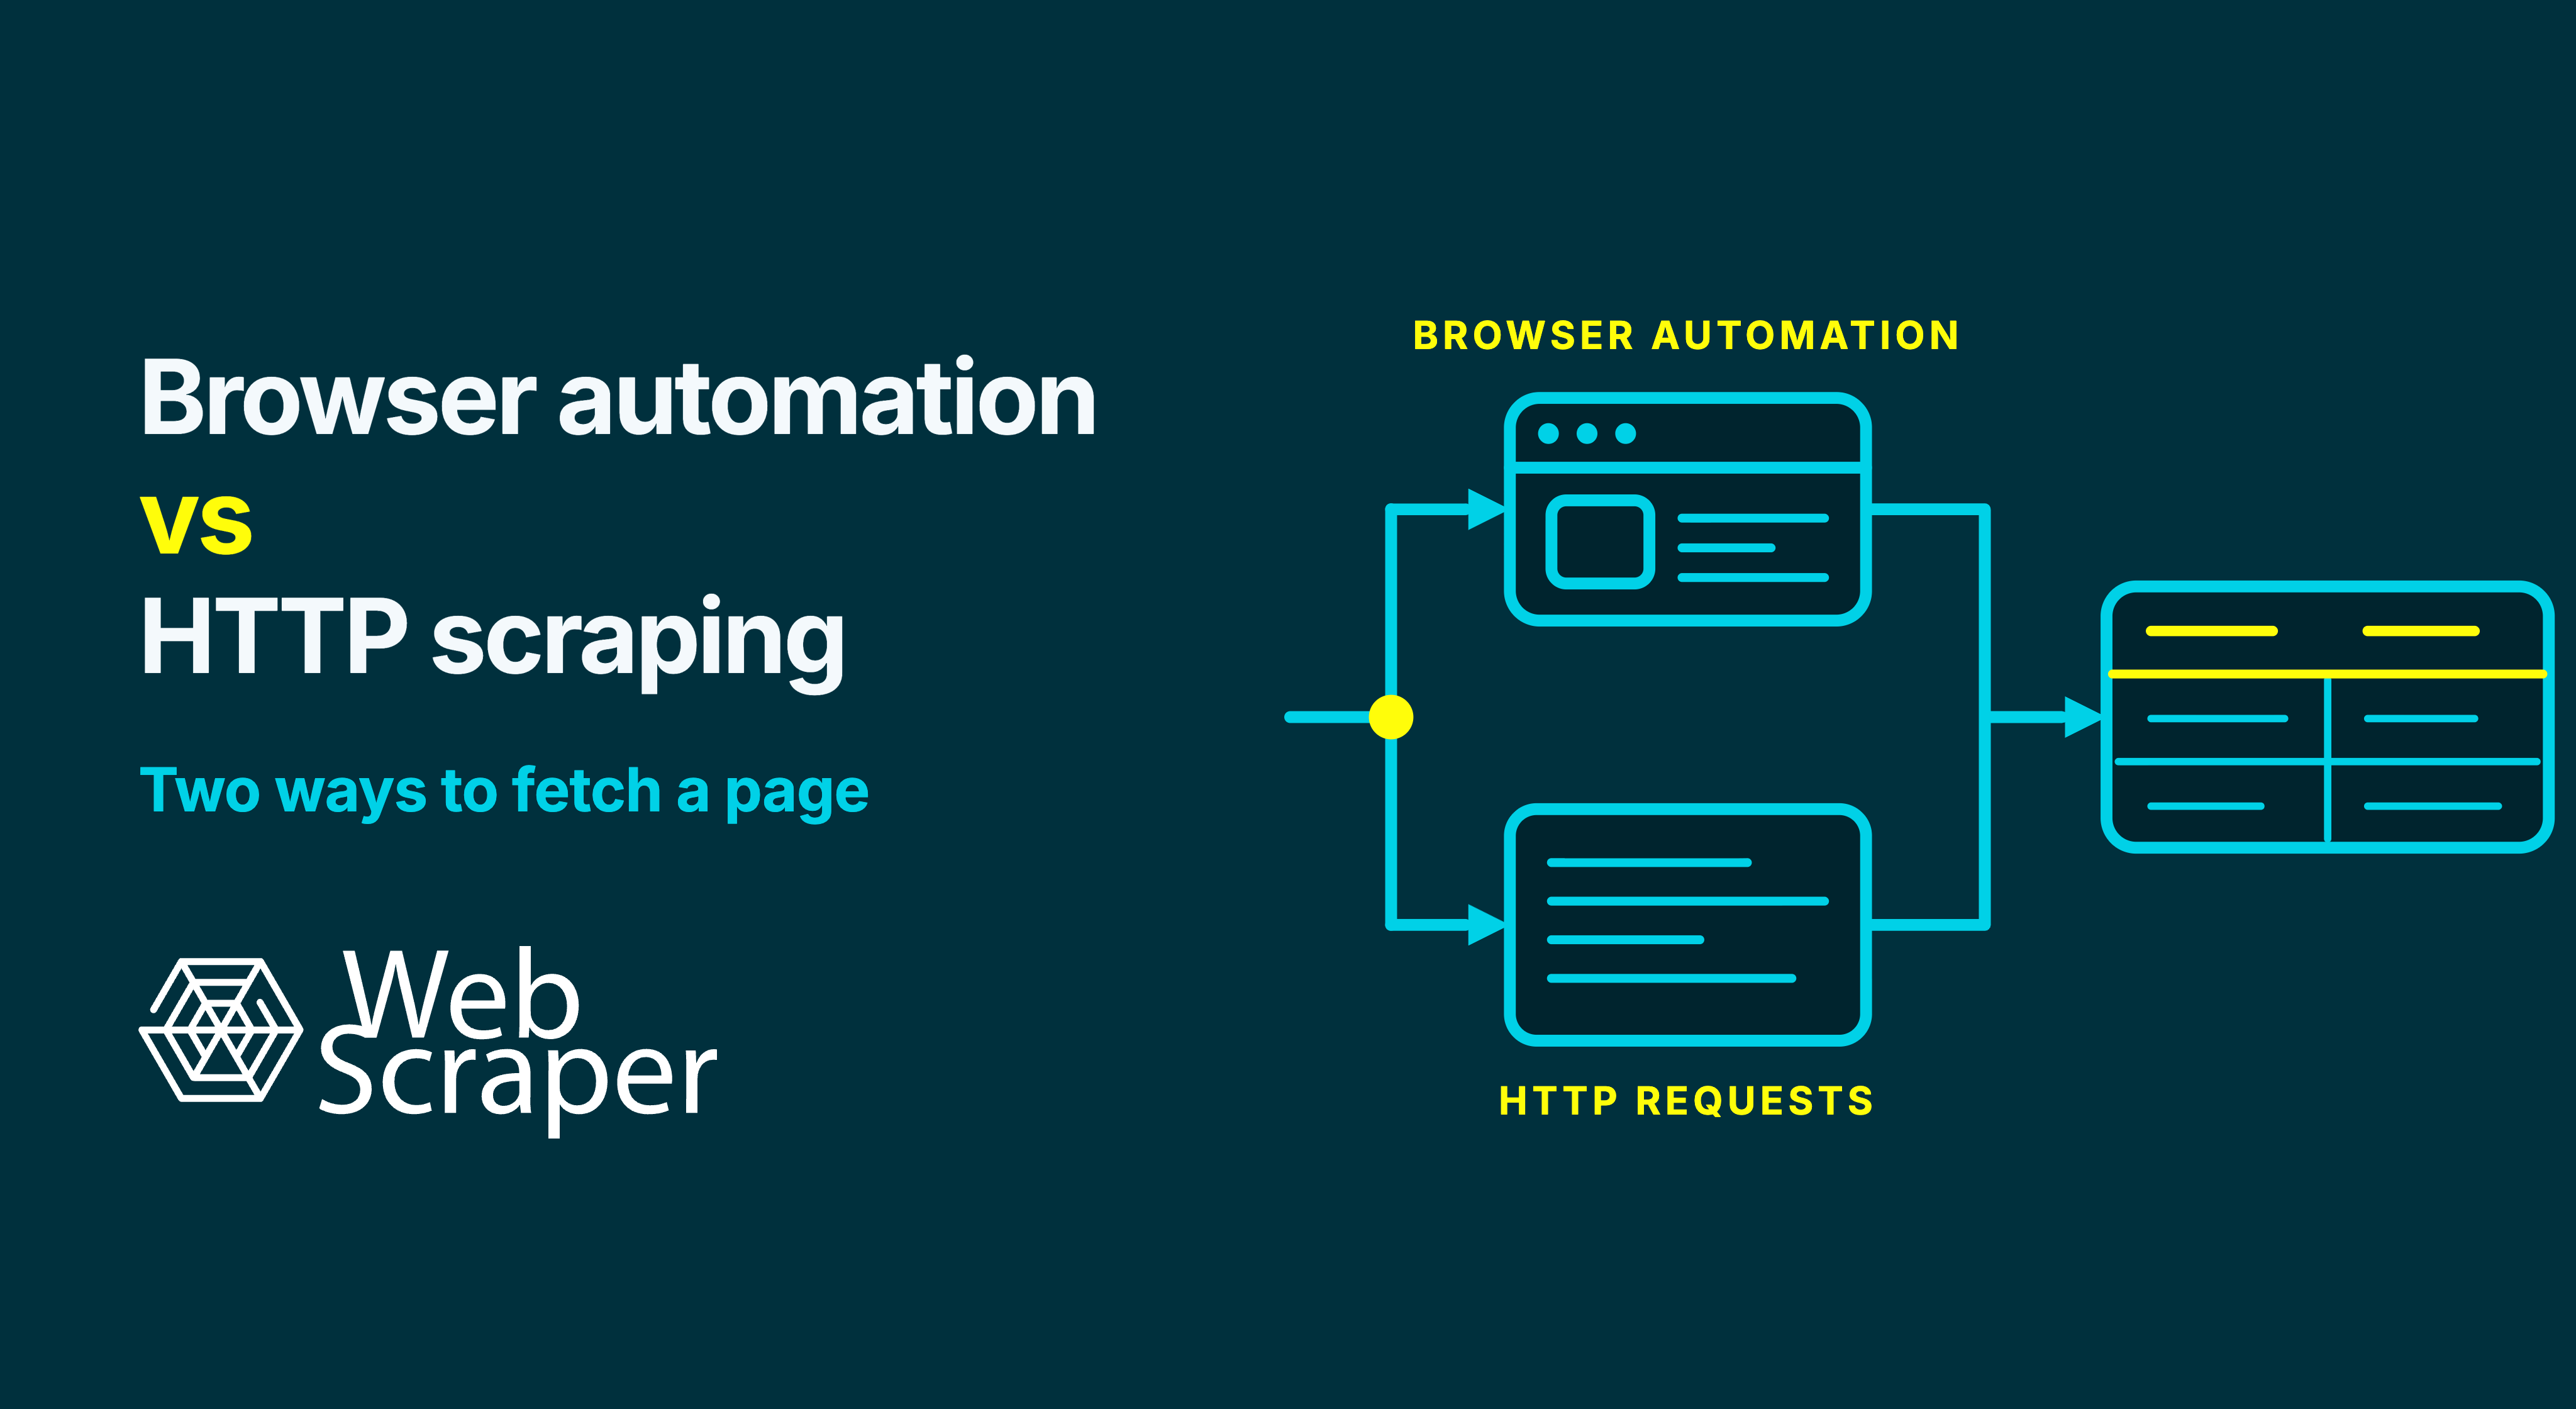
Use HTTP scraping when the response already contains every required record, field and link. Use browser automation when JavaScript or an interaction must create the data or page state first.

The decision should follow the dataset you need, not whether the website merely uses JavaScript. On mixed sites, separate HTTP and browser routes often provide the clearest balance of reliability, scale and maintainability.

Continue Reading

Web Scraper vs Thunderbit

August 25, 2026

web scraper, Web Scraper Cloud, web scraping

Web Scraper is the stronger choice for repeatable, structured data pipelines. Thunderbit is better for quick AI-assisted browser-to-spreadsheet extraction.

The key difference is control: Web Scraper prioritises reusable, inspectable workflows, while Thunderbit prioritises speed and minimal setup.

Continue Reading

What is the easiest way to scrape a website?

August 25, 2026

data extraction, Web Scraper Cloud, web scraping
For a few values on one page, the easiest method is copy and paste. For a repeatable structured dataset, the easiest way to scrape a website is usually an AI-assisted no-code browser extension. It lets you work on the live page, test the result and reuse the extraction setup without maintaining a custom script.

The simplest first attempt is not always the simplest long-term method. Pagination, JavaScript, multiple page layouts and access restrictions can turn an apparently easy scraper into an ongoing engineering task. Choose the least complex method that can still return every required record and field when you run it again.

Continue Reading

How to collect product names, prices and SKUs

August 24, 2026

Web scraping platforms, web scraping tools, E-commerce
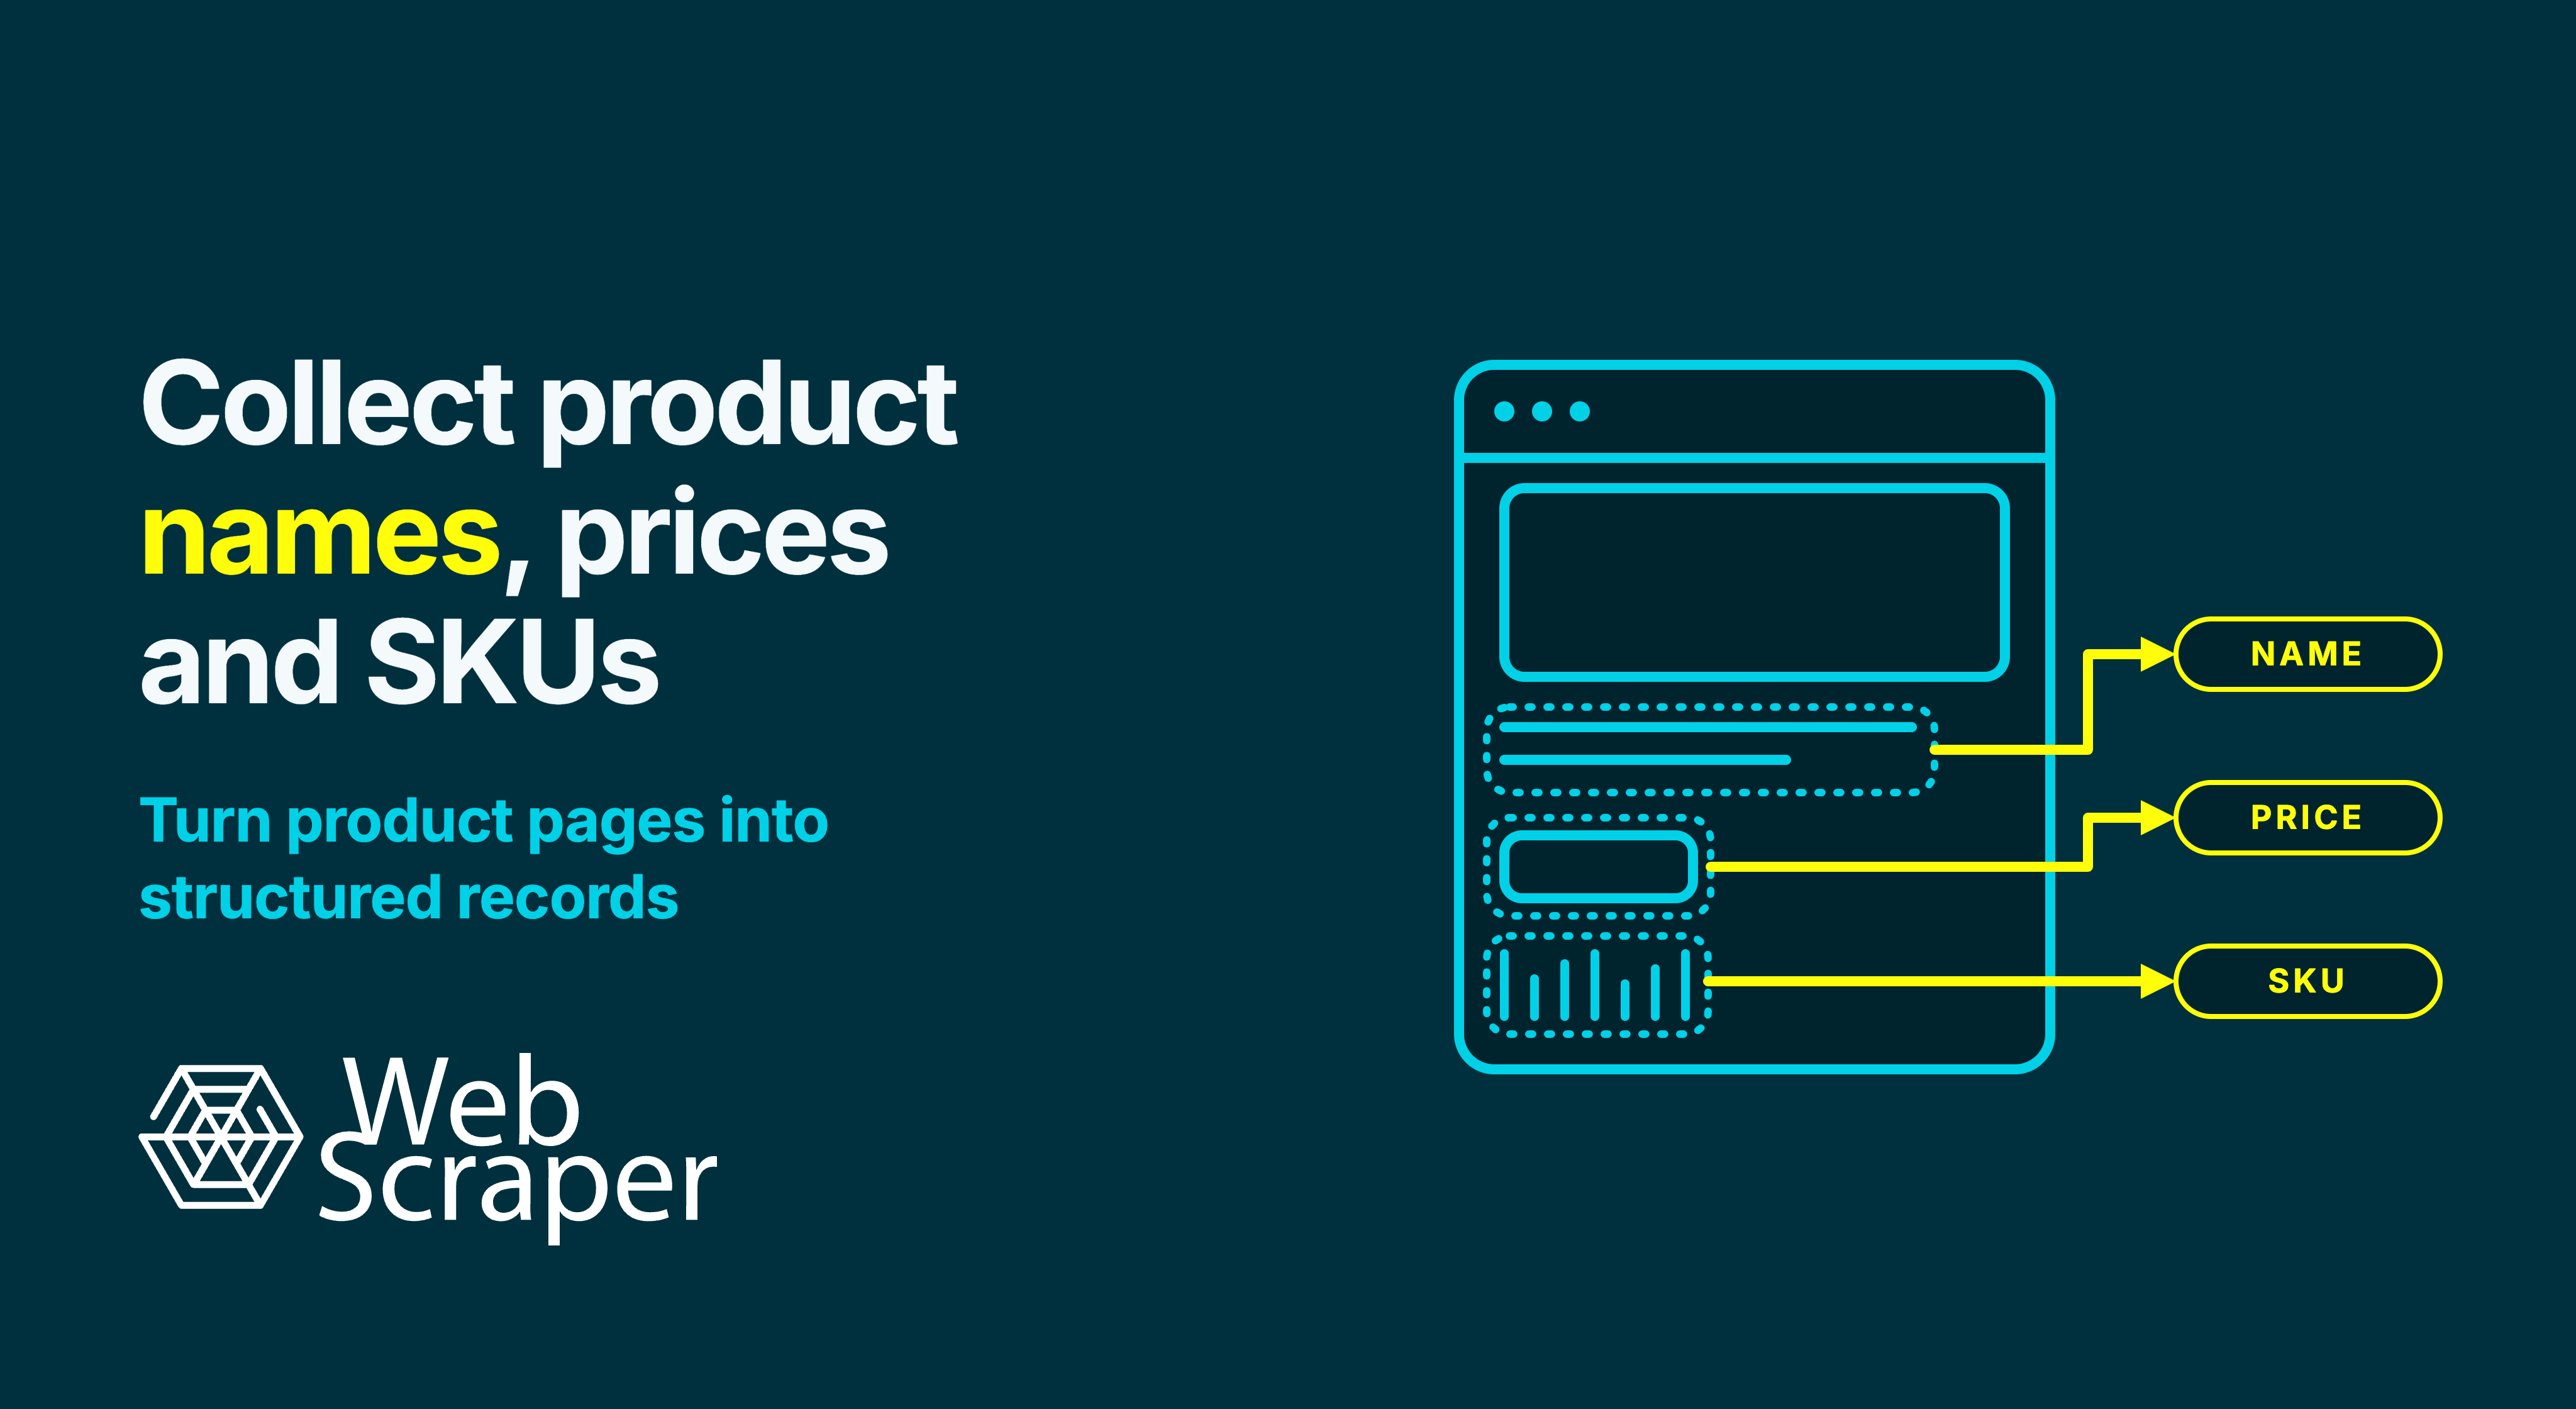
Product names and prices are often visible on category pages, while SKUs may appear only on individual product pages. Select a different size or colour, and the SKU and price may change again.

The main challenge is therefore not extracting three pieces of text. It is producing one reliable record per product or variant, with the correct name, price and SKU kept together.

This guide explains how to structure that workflow with Web Scraper, follow products from listing pages to their details, handle variants and sale prices, and validate the resulting dataset before export or automation.

Continue Reading

Web Scraper vs Firecrawl

August 24, 2026

Data extraction tool, data extraction, web scraping tools, Web Scraper Cloud, web scraping
Web Scraper is the stronger choice for repeatable, structured datasets, offering reusable sitemaps, data-quality controls, automation and substantially lower Scale pricing. Firecrawl is better suited to arbitrary URL requests, Markdown crawling and RAG workflows.

Disclosure: This comparison is published by Web Scraper, but both products have been assessed fairly.

Continue Reading

Web Scraper vs Octoparse: Which no-code scraper should you choose?

August 24, 2026

Web scraping platforms, web scraper, no-code scraping, Comparison
Web Scraper and Octoparse are no-code web scraping tools that can turn multi-page websites into structured datasets. Both provide automatic field detection, visual configuration, local extraction and paid cloud automation, but they organise and scale scraping workflows differently.

Octoparse is the better choice when a ready-made template already covers the exact website and fields you need, or when your team prefers a desktop application with an action-based workflow. Web Scraper is better when the job requires custom extraction logic, linked detail pages, free unrestricted local prototyping, explicit data-quality controls or a transparent path to high-volume cloud execution.

Continue Reading

Ethical request rates: How much scraping traffic is too much?

August 20, 2026

request rates, rate limiting, web scraping

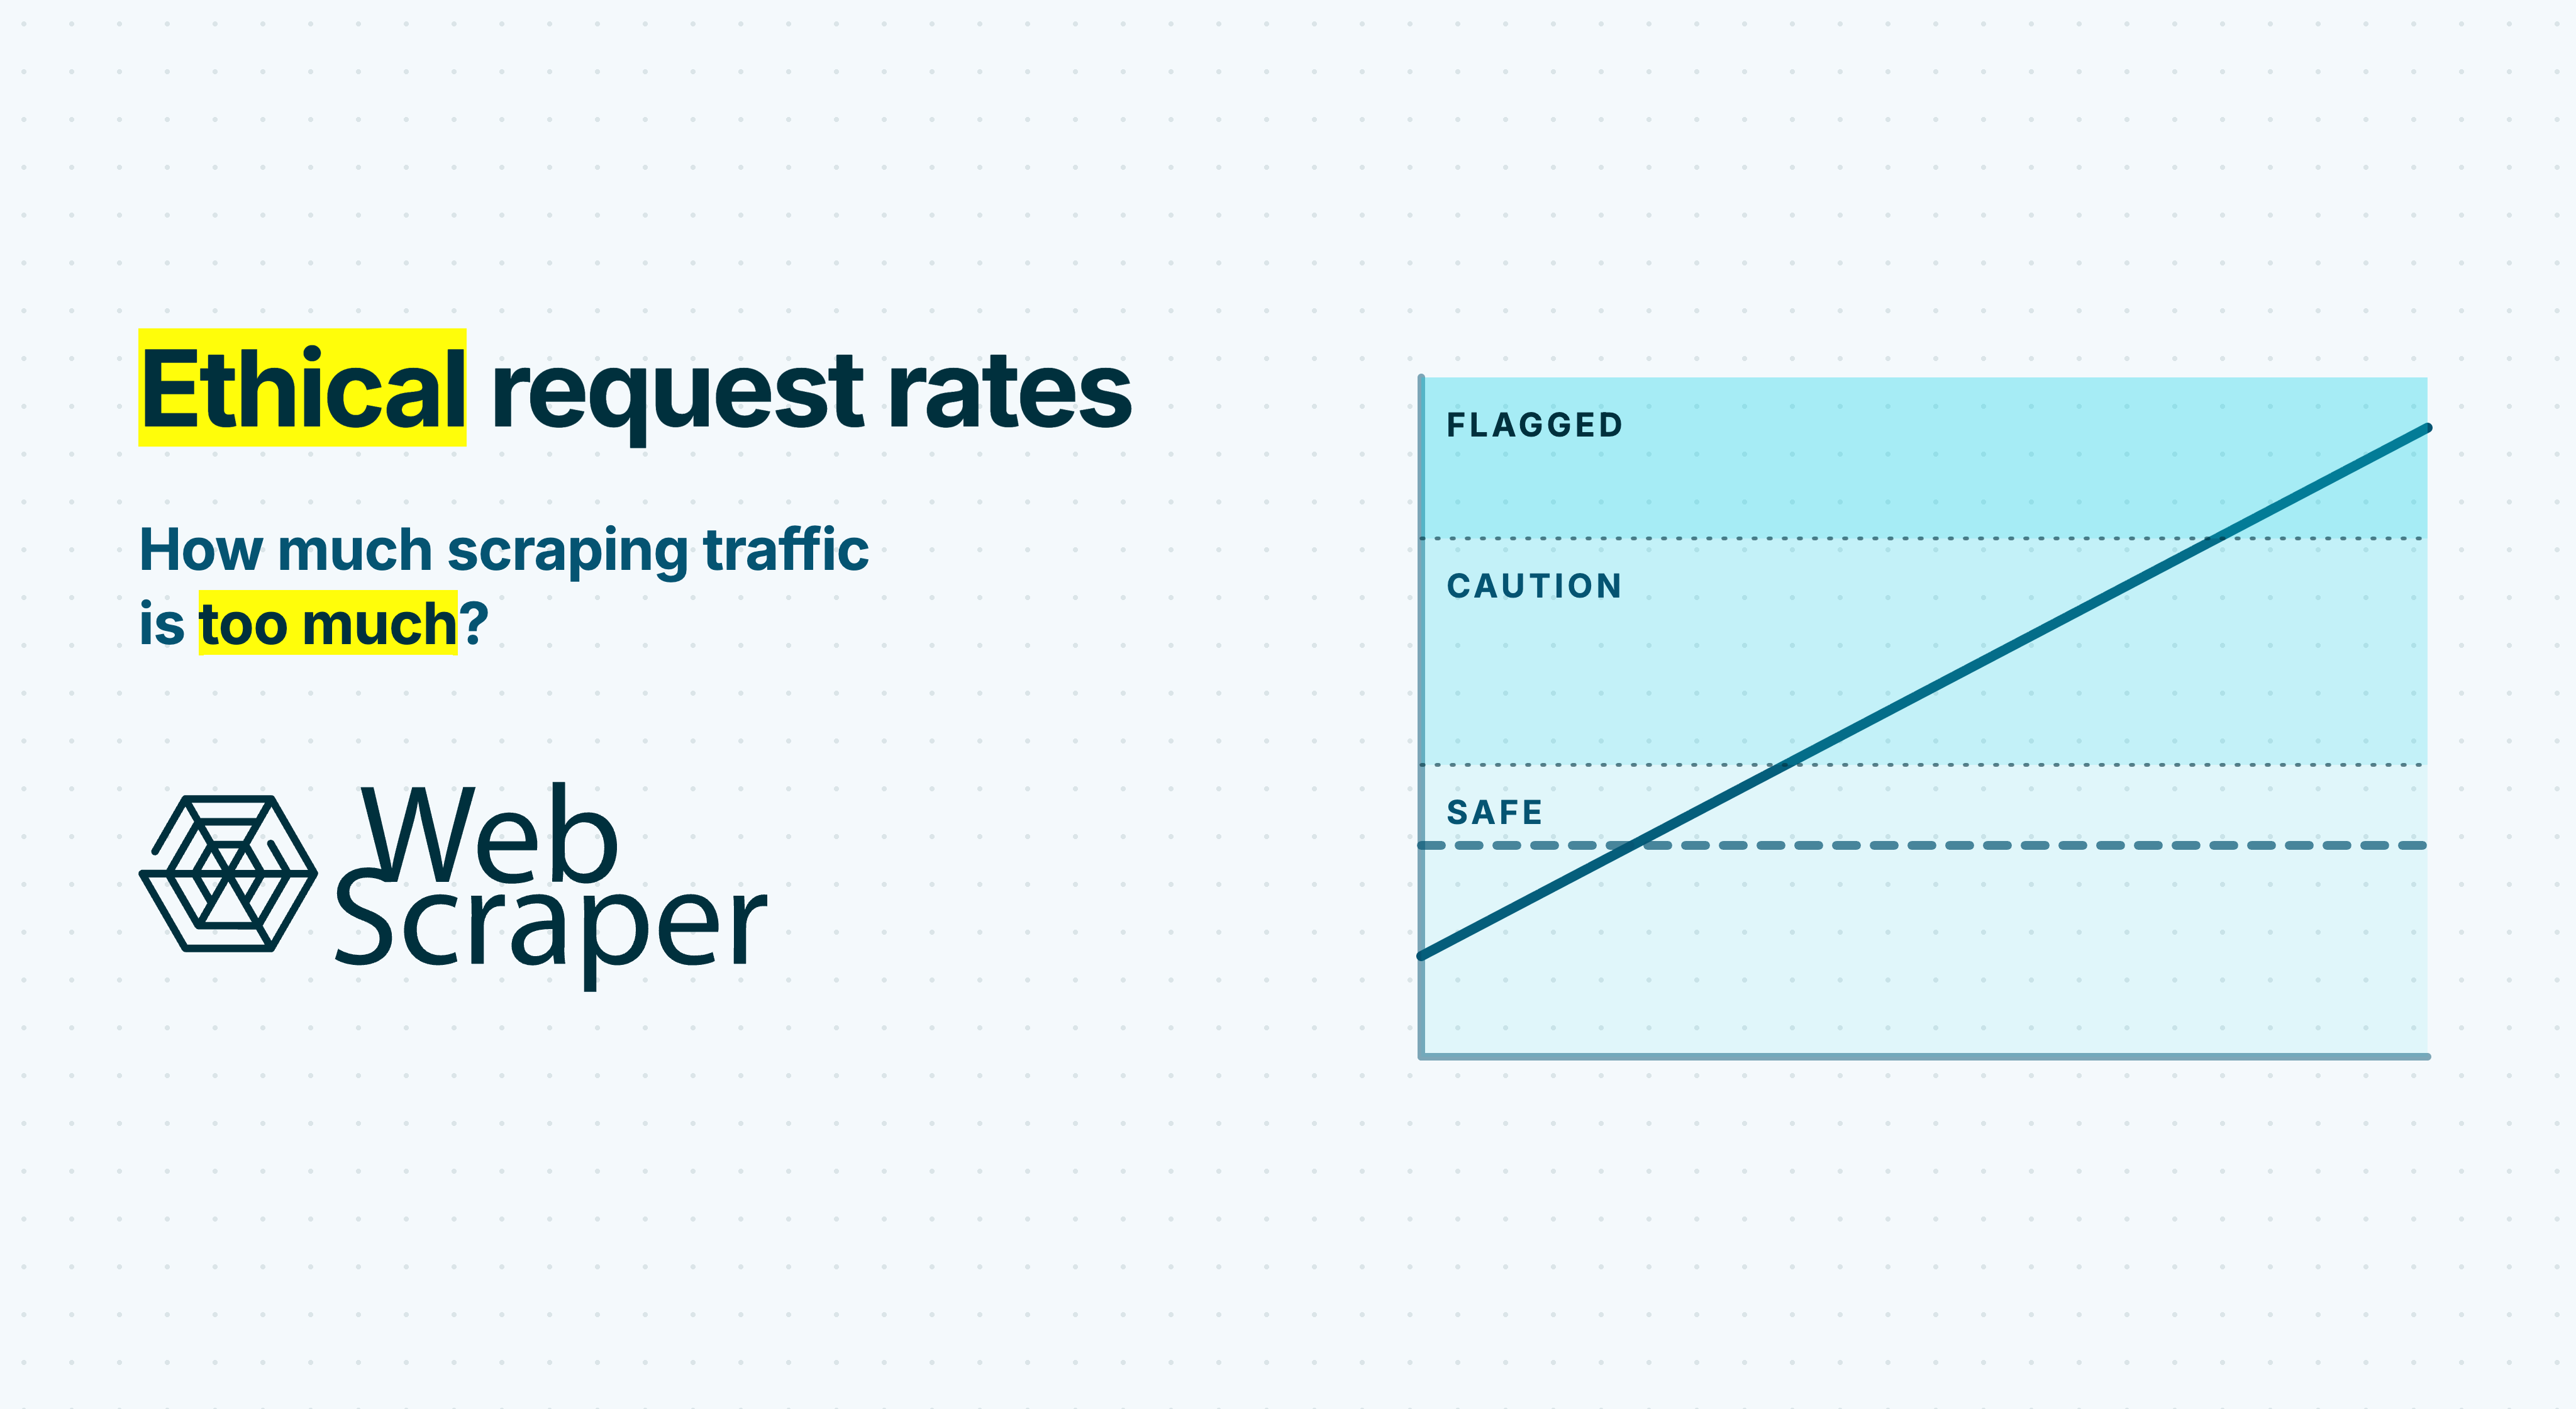
One request per second can be harmless to one website and excessive for another. A public data service may permit ten requests per second, while a small website could struggle with a short burst at a fraction of that rate.

If an ordinary public website provides no limit, a cautious starting point is one concurrent page navigation per hostname with two to five seconds between page starts. Use five to ten seconds or longer for a small, community-run or unknown-capacity site.

These are starting heuristics, not permission. Follow the lowest applicable limit from the website, an agreement, observed server behaviour or the project’s actual requirements.

Continue Reading