Blog
August 04, 2026
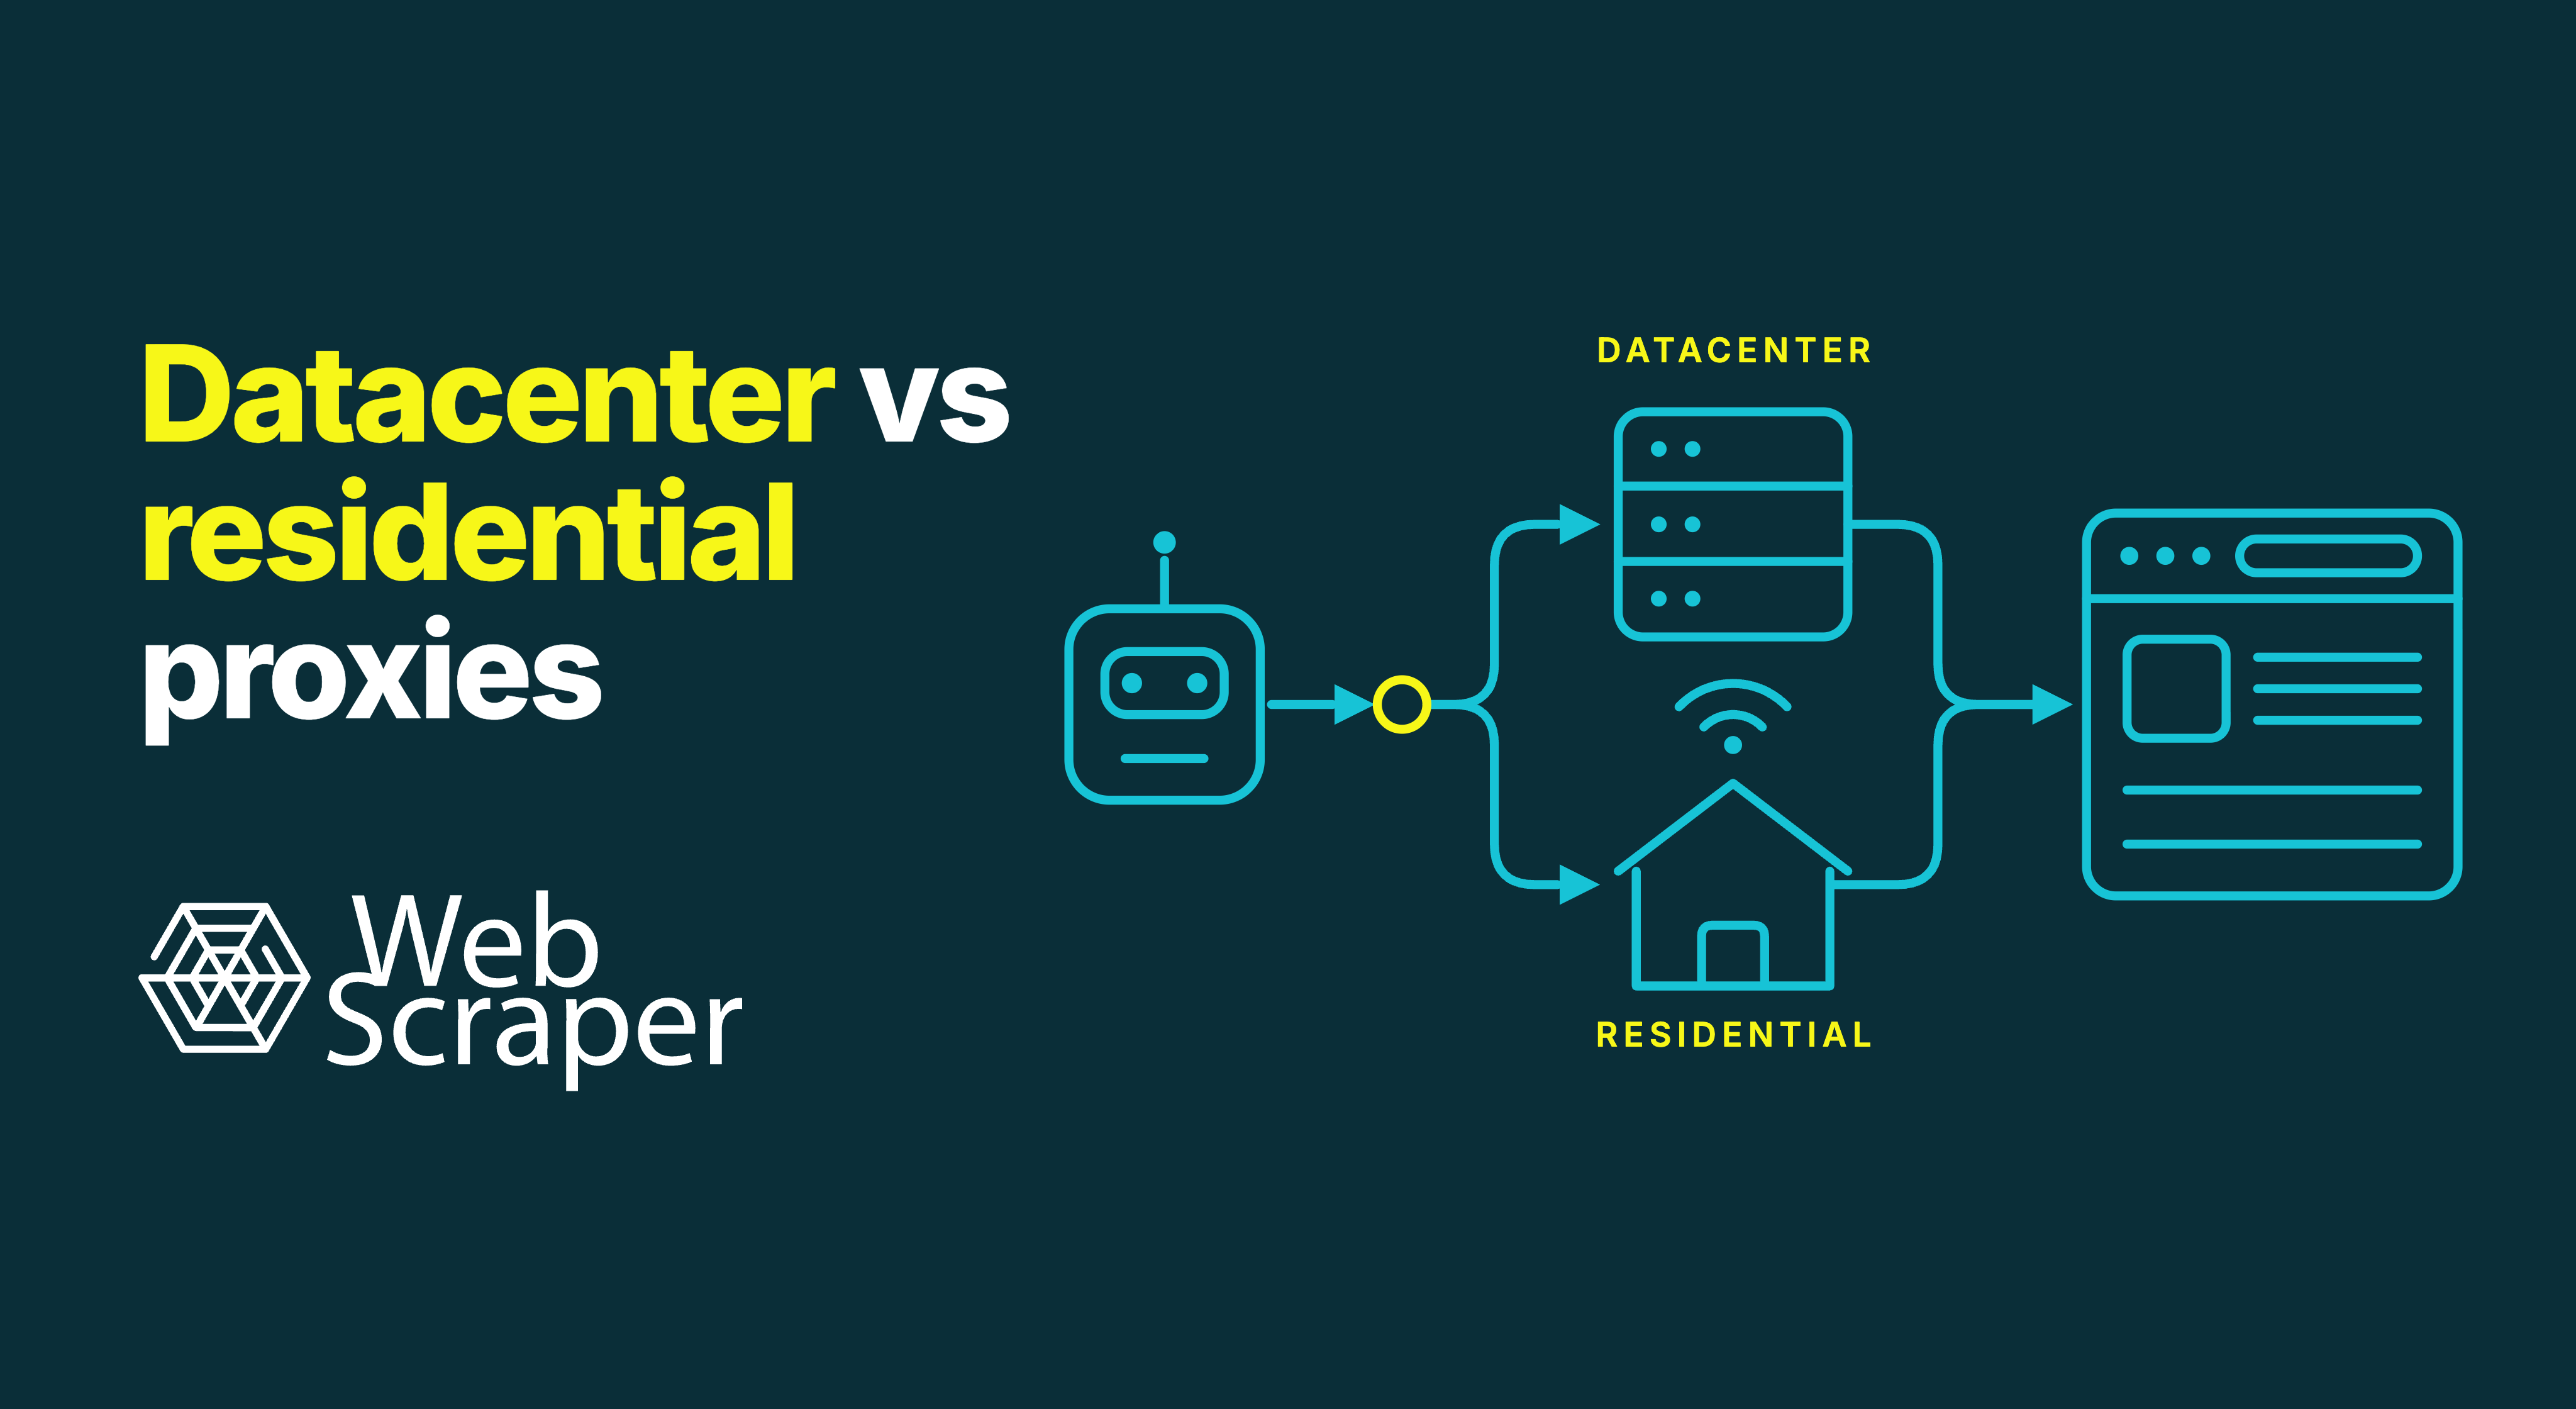
web scraping reliability, data quality, Proxy management
August 04, 2026
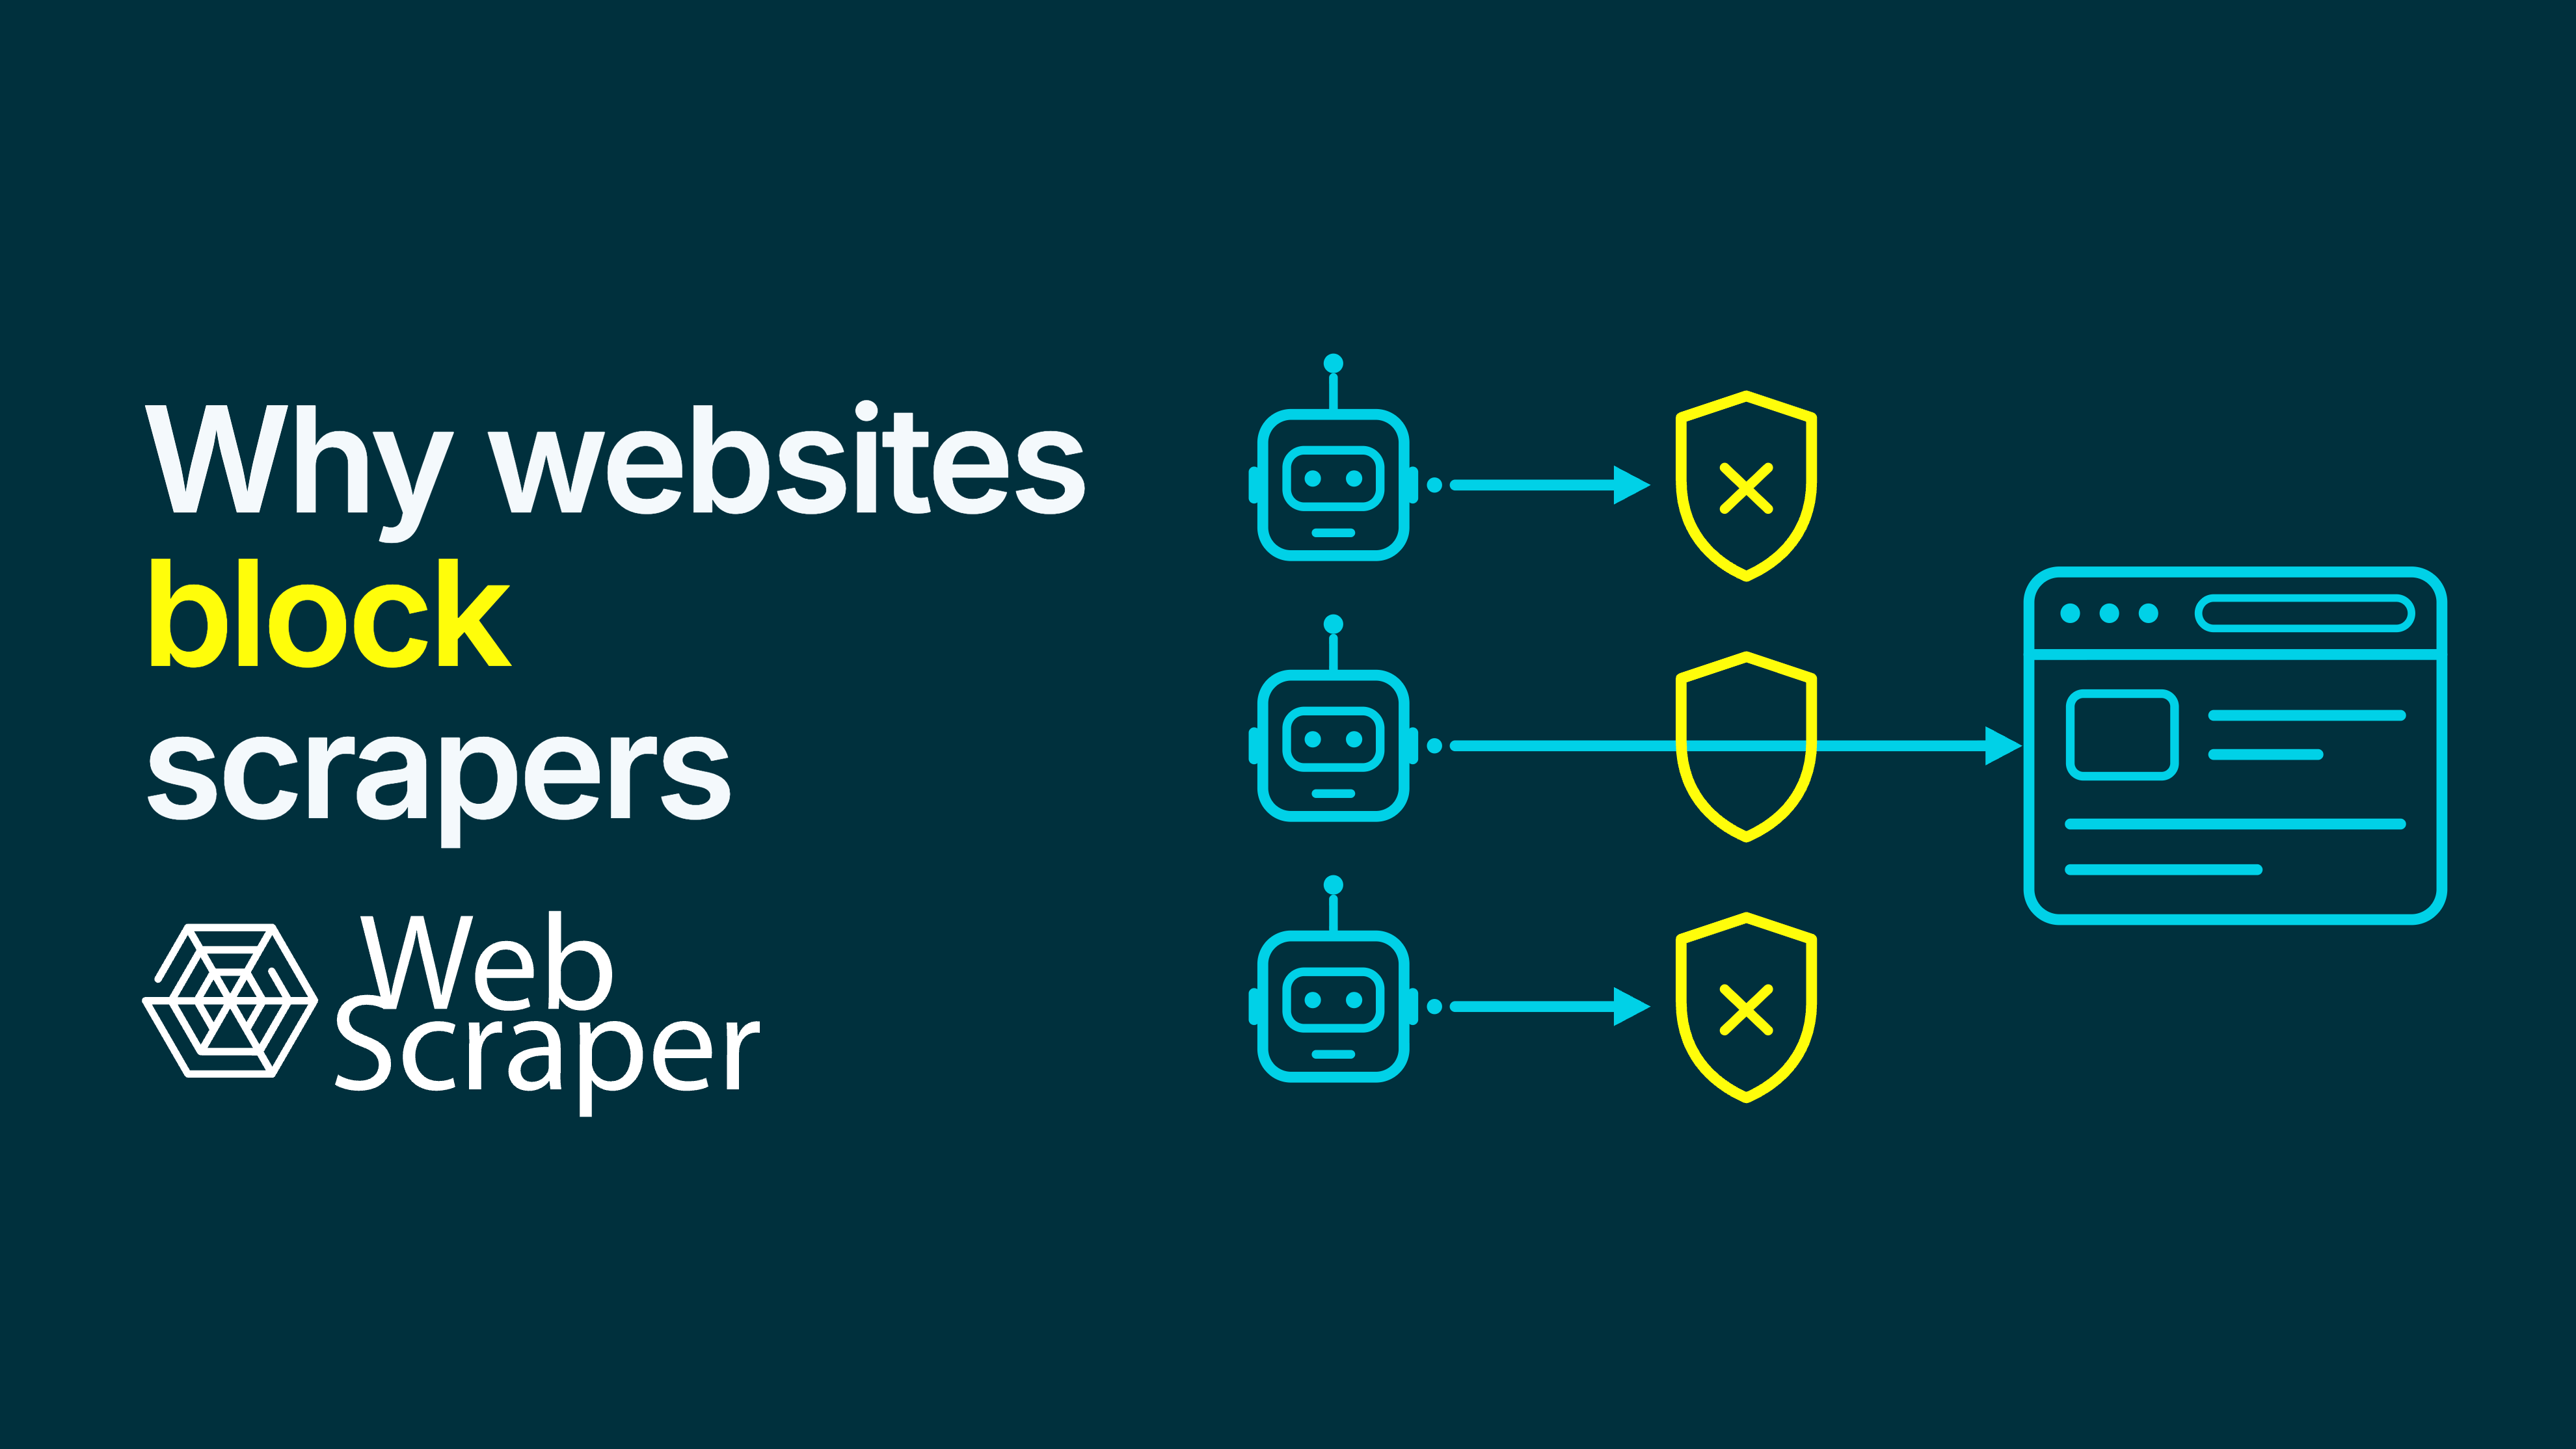
Anti-bot, bot detection, rate limiting, Proxies, web scraping
August 04, 2026
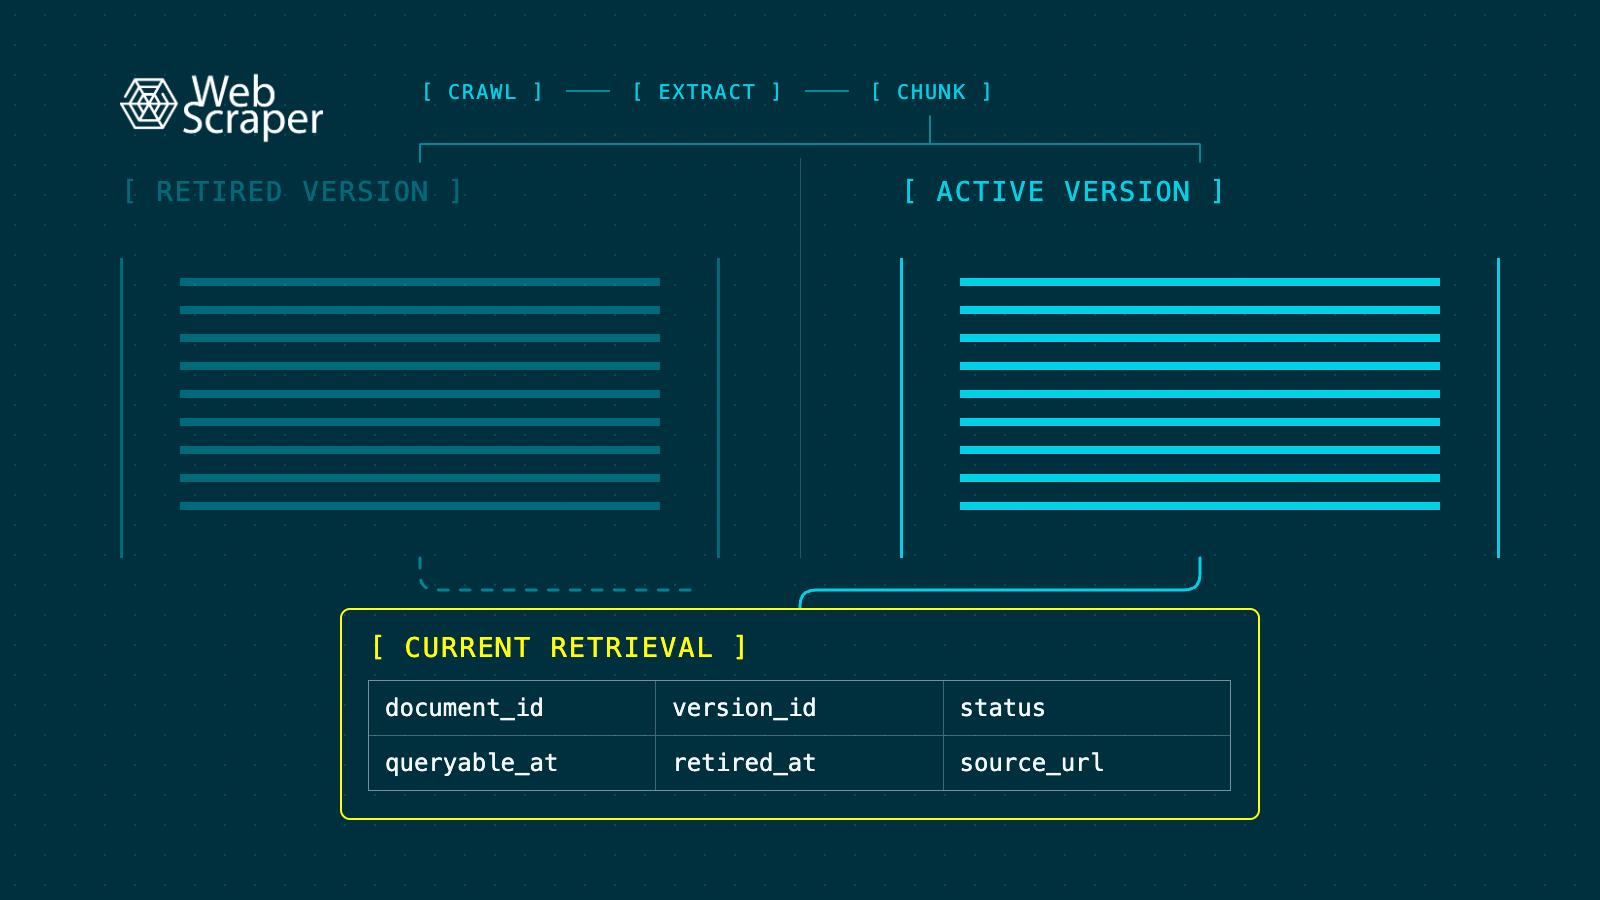
vector databases, data pipelines, web data, AI, RAG
August 04, 2026
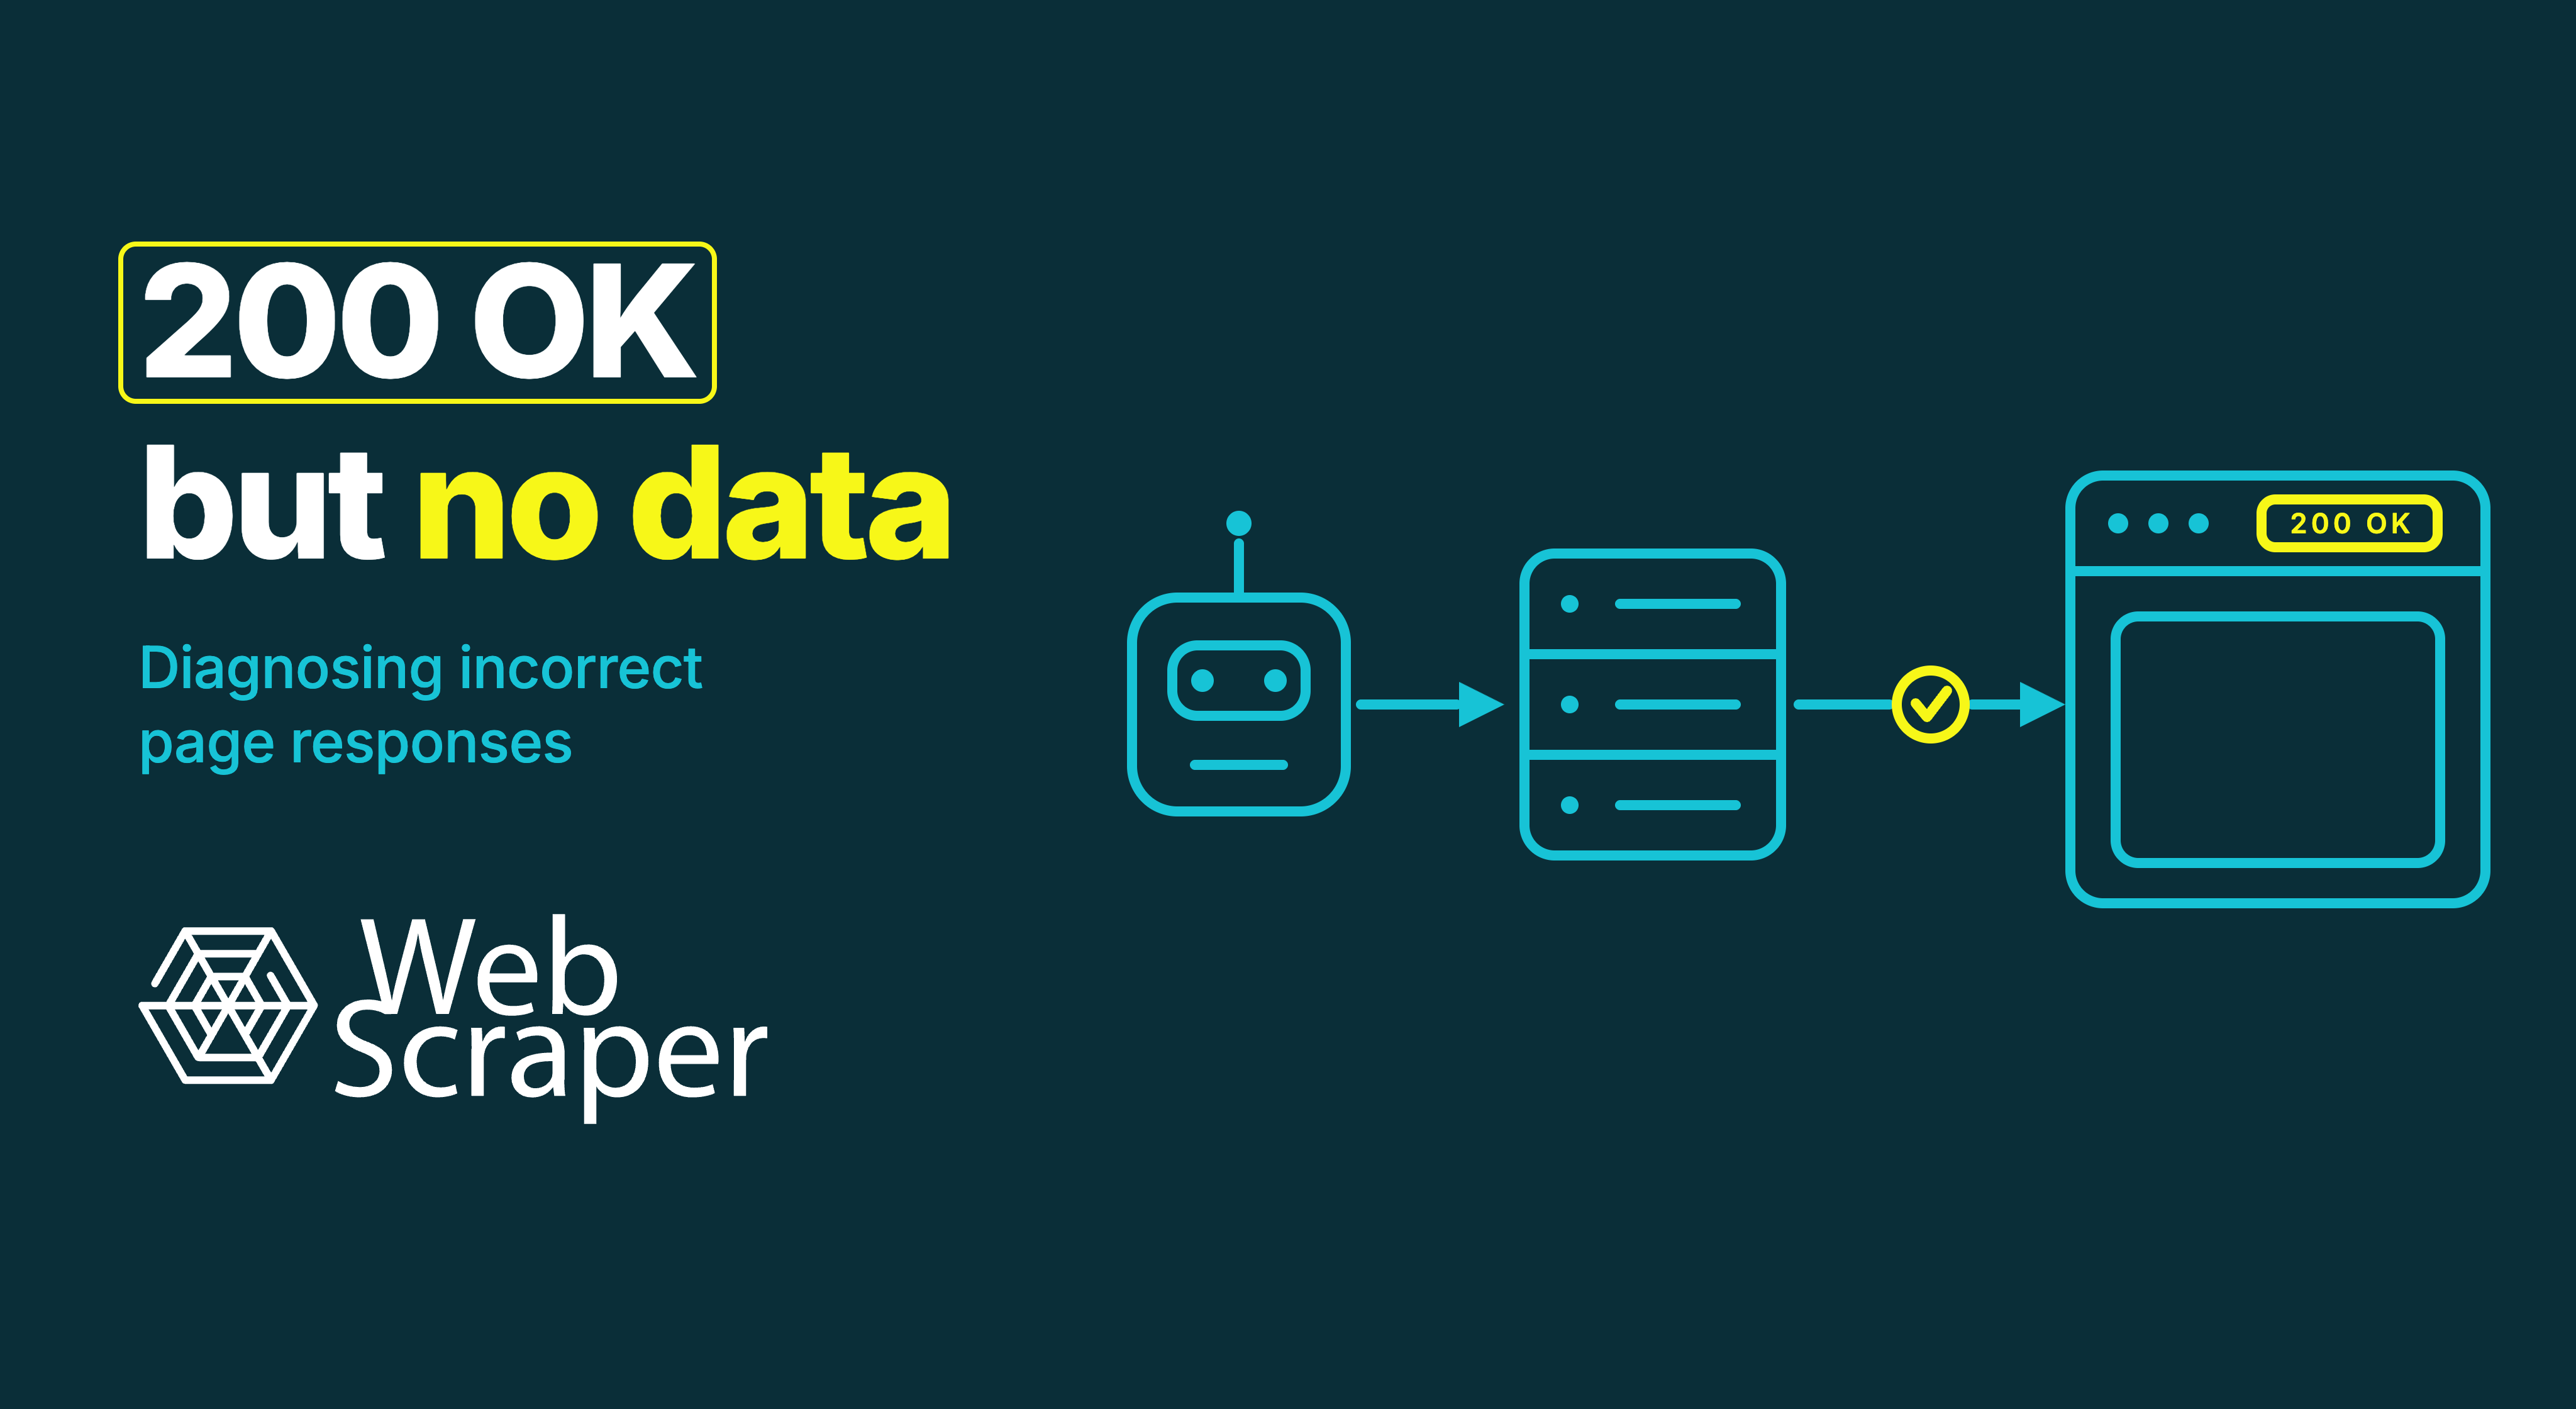
Data validation, Empty scraping results, 200 OK, JavaScript rendering, Soft blocks
August 03, 2026
Web Scraper Cloud, Data collection, API
July 20, 2026
We are happy to announce that Web Scraper 1.111.13 has been released. This update introduces several improvements to the AI Wizard, enhances CSS selector generation for pagination, expands language support, and includes fixes for element selection within shadow roots.
July 08, 2026
Anti-bot, Proxies, HTTP/3
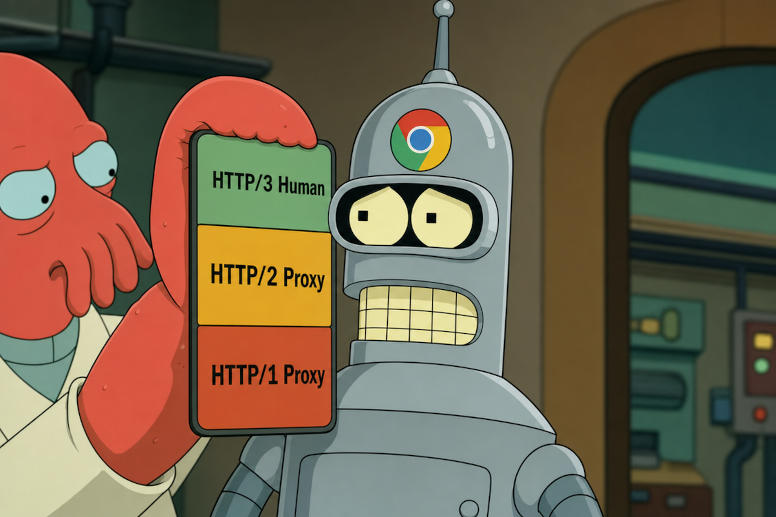
Practically all modern browsers support HTTP/3, and all of the biggest CDN providers have enabled HTTP/3 support as of 2022. However, only 34.7% of top 1000 websites (CloudFlare’s top domains 2026-05 list manually verified) support HTTP/3, but website support is growing year by year. Even though HTTP/3 over QUIC is a fundamental web content delivery change, the adoption is meaningful, and HTTP/3 is propagating everywhere.
Proxies are a major part of web scraping as they allow for more anonymity, privacy and access to sites that may be protected in various ways like geo-blocking and client fingerprinting. The biggest proxy vendors support proxying web traffic via HTTP or (sometimes) SOCKS5 proxies, but this support is largely limited to TCP, while HTTP/3 over QUIC is delivered over UDP. Some SOCKS5 proxies might support HTTP/3 by allowing proxying of UDP traffic, but since browsers do not support the configuration of UDP proxies, there is no easy way to proxy HTTP/3 traffic.
March 16, 2026
The Better Business Bureau (BBB) maintains a large public directory of business profiles across the United States and Canada, where companies are listed together with ratings, contact information, and customer feedback. These listings provide structured details such as business names, locations, phone numbers, categories, and links to full company profiles that include BBB ratings and additional background information. In this guide, you will learn how to use Web Scraper to collect BBB business listings from search result pages and extract structured company data from both listings and profile pages without writing code. The extracted dataset can then be exported in CSV, Excel, or JSON format and used for business research, lead generation, competitive analysis, or building structured business directories.
March 13, 2026
Copart is a large online vehicle auction platform where thousands of cars are listed through searchable inventory pages. These pages display structured information such as vehicle titles, lot numbers, auction locations, current bids, sale status, and links to individual vehicle pages. In this guide, you will learn how to scrape Copart vehicle listings using Web Scraper and collect structured vehicle data directly from search result pages without writing code. The extracted data can be exported in CSV, Excel, or JSON formats and used for vehicle market analysis, auction monitoring, inventory research, or integration into other systems.
March 10, 2026
Trustpilot is one of the largest online review platforms, hosting millions of company profiles where customers share ratings and feedback about businesses across industries. Trustpilot company listings contain structured information such as company names, TrustScore ratings, review counts, categories, and links to company websites. In this guide, you will learn how to scrape Trustpilot company listings using Web Scraper and extract structured company data directly from category and listing pages without writing code. The collected data can be exported in CSV, Excel, or JSON formats for further analysis, reputation monitoring, market research, or integration into other systems.
March 09, 2026
Amazon product listings can be accessed through both search results and category pages, where products are organised by keyword queries or product categories. These listing pages display structured information such as product titles, prices, ratings, and links to individual product pages. In this guide, you will learn how to scrape Amazon product listings using Web Scraper and extract structured product data from listing pages and product detail pages without writing code. The scraper can start from either an Amazon search results page or a category page and collect product information across multiple listings, with the extracted data exported in CSV, Excel, or JSON formats for further analysis, storage, or integration into other systems.
March 09, 2026
DIY.com is the online store of the British home improvement retailer B&Q and offers a large catalogue of products across categories such as tools, building materials, kitchens, bathrooms, flooring, and garden equipment. Product listings on DIY.com contain structured information such as product names, prices, ratings, descriptions, images, and category data. In this guide, you will learn how to scrape DIY.com product listings using Web Scraper and extract structured product data directly from category pages and product detail pages without writing code. The extracted data can be exported in CSV, Excel, or JSON formats for further analysis, price monitoring, product research, or integration into other systems.
March 06, 2026
Realtor.com is one of the largest online real estate platforms used to explore homes for sale, rental properties, and housing market information across different locations. Property listings on Realtor.com contain structured information such as listing prices, property details, locations, images, and real estate agent information. In this guide, you will learn how to scrape Realtor.com property listings using Web Scraper and extract structured real estate data directly from search result pages and property detail pages without writing code. The extracted data can be exported in CSV, Excel, or JSON formats for further analysis, real estate market research, price monitoring, or integration into other systems.
March 06, 2026
Amazon Bestsellers pages list the top-selling products within each category and are widely used to monitor product trends, analyse market demand, track competitors, and identify high-performing items. In this guide, you will learn how to scrape Amazon Bestsellers data using Web Scraper and extract structured product information directly from listing and product pages without writing code. The extracted data can be exported in CSV, Excel, or JSON for further analysis, storage, or integration into other systems.
March 06, 2026
Yellow Pages is one of the largest online business directories and is widely used to discover companies, local services, and contact information across industries and locations. Yellow Pages listings contain structured data about businesses, including company names, phone numbers, addresses, ratings, and service categories. In this guide, you will learn how to scrape Yellow Pages business listings using Web Scraper and extract structured business data directly from search result pages and business profiles without writing code. The extracted data can be exported in CSV, Excel, or JSON formats for further analysis, lead generation, market research, or integration into other systems.